# A tibble: 1,000 × 11
      id referrer device bouncers n_visit n_pages duration country      purchase
   <dbl> <chr>    <chr>  <lgl>      <dbl>   <dbl>    <dbl> <chr>        <lgl>
 1     1 google   laptop TRUE          10       1      693 Czech Repub… FALSE
 2     2 yahoo    tablet TRUE           9       1      459 Yemen        FALSE
 3     3 direct   laptop TRUE           0       1      996 Brazil       FALSE
 4     4 bing     tablet FALSE          3      18      468 China        TRUE
 5     5 yahoo    mobile TRUE           9       1      955 Poland       FALSE
 6     6 yahoo    laptop FALSE          5       5      135 South Africa FALSE
 7     7 yahoo    mobile TRUE          10       1       75 Bangladesh   FALSE
 8     8 direct   mobile TRUE          10       1      908 Indonesia    FALSE
 9     9 bing     mobile FALSE          3      19      209 Netherlands  FALSE
10    10 google   mobile TRUE           6       1      208 Czech Repub… FALSE
# ℹ 990 more rows
# ℹ 2 more variables: order_items <dbl>, order_value <dbl>
2.2.2 Data Dictionary
id: row id
referrer: referrer website/search engine
device: device used to visit the website
bouncers: whether the visit bounced (single page viewed)
n_visit: number of visits
n_pages: number of pages visited
duration: time spent on the website (in seconds)
country: country of origin
purchase: whether visitor purchased
order_items: number of items ordered
order_value: order value of visitor (in dollars)
2.3 Point
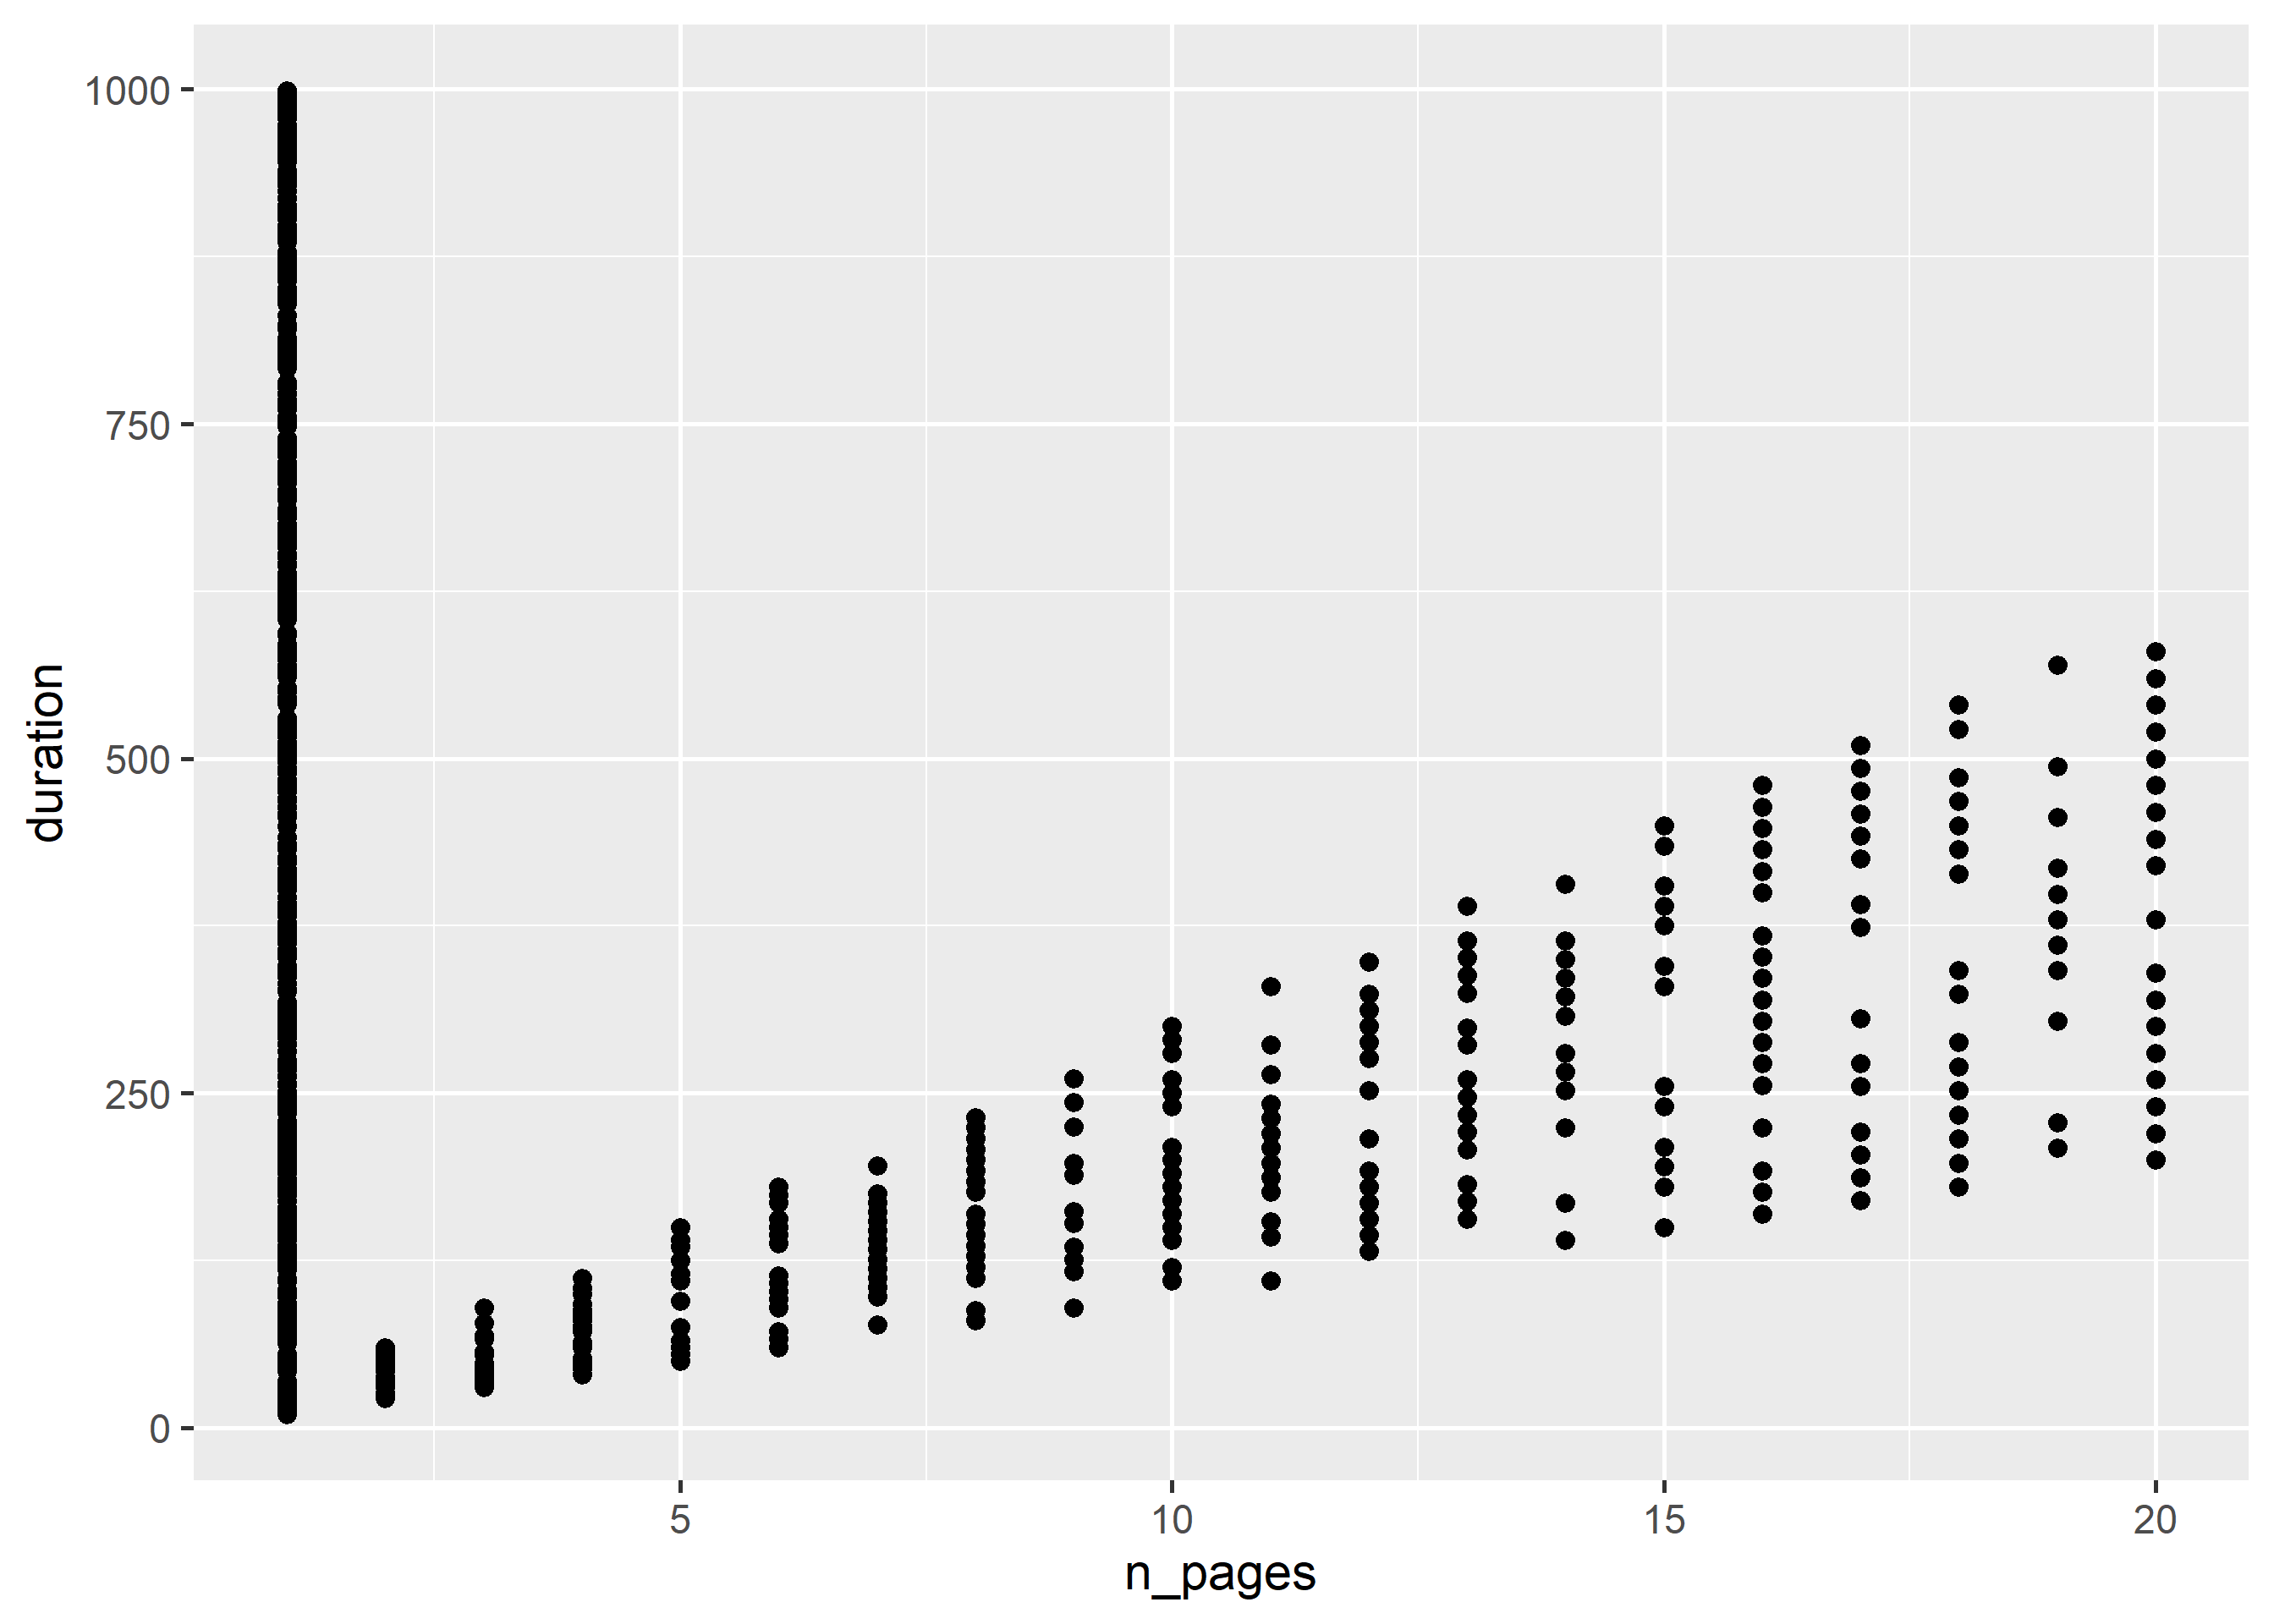
A scatter plot displays the relationship between two continuous variables. In ggplot2, we can build a scatter plot using geom_point(). Scatter plots can show you visually
the strength of the relationship between the variables
the direction of the relationship between the variables
and whether outliers exist
The variables representing the X and Y axis can be specified either in ggplot() or in geom_point(). We will learn to modify the appearance of the points in a different post.
ggplot(ecom, aes(x = n_pages, y = duration)) +geom_point()
2.4 Regression Line
A regression line can be fit using either:
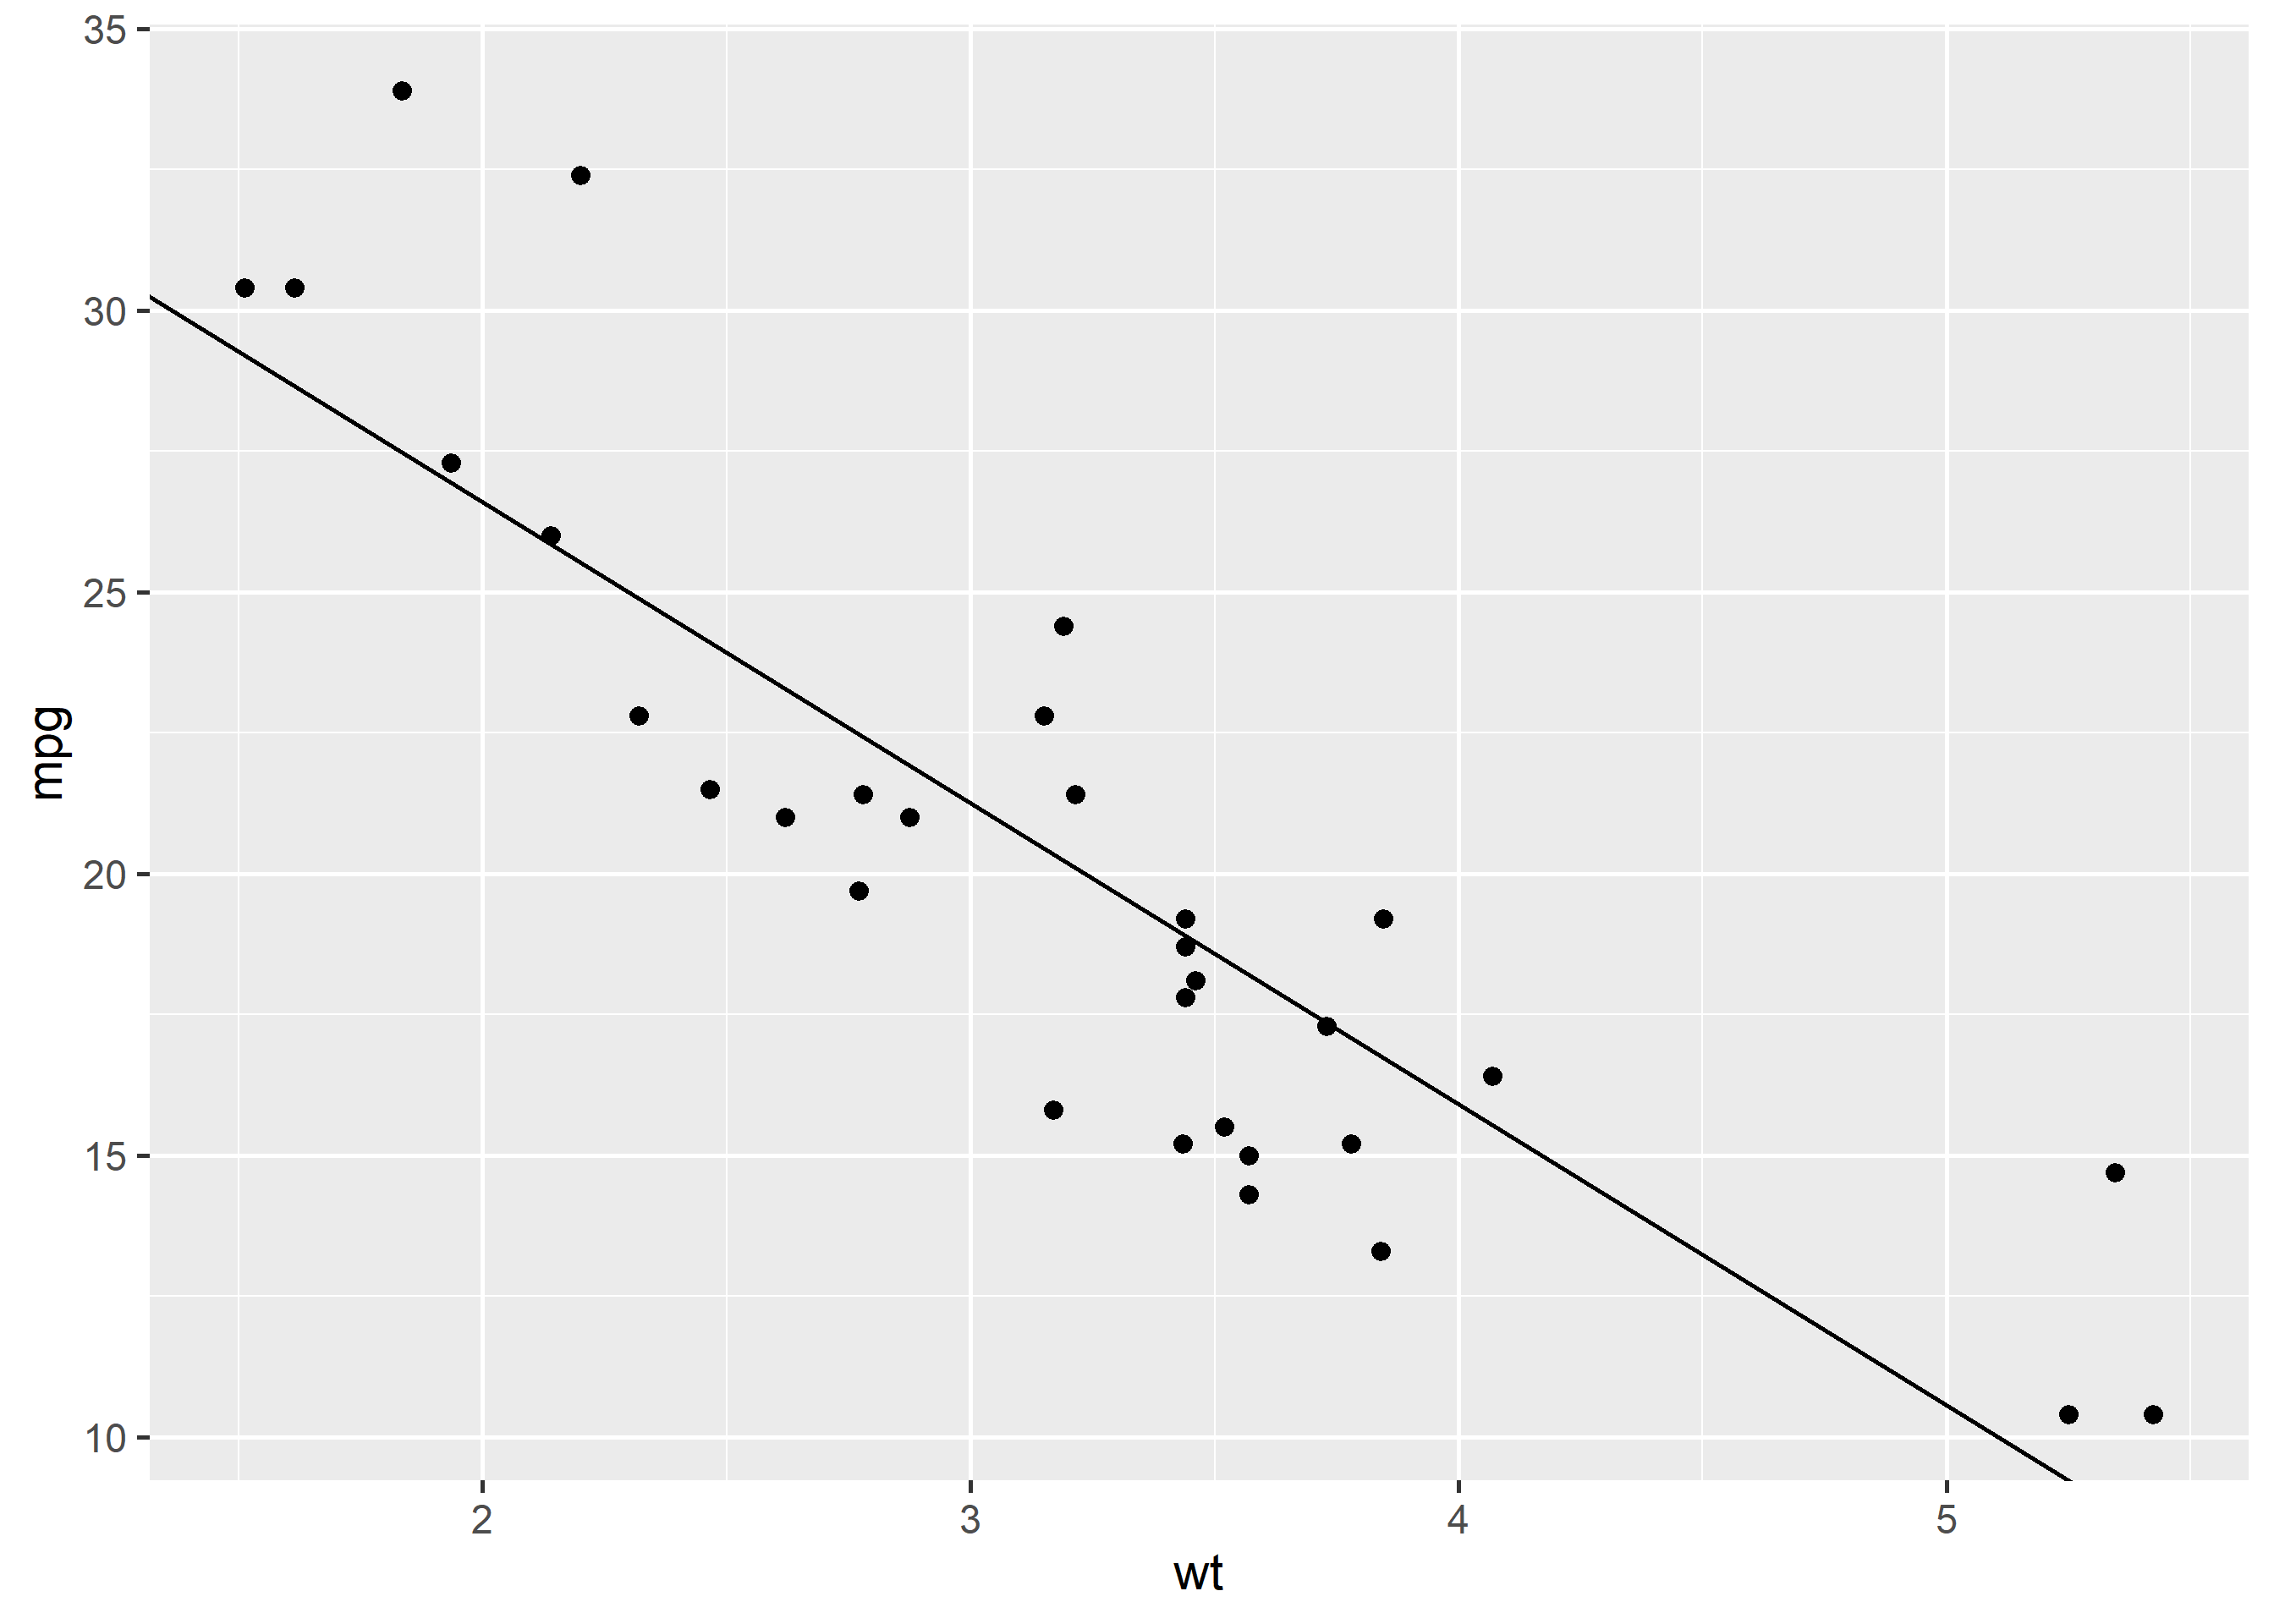
geom_abline()
geom_smooth()
If you are using geom_abline(), you need to specify the intercept and slope as shown in the below example:
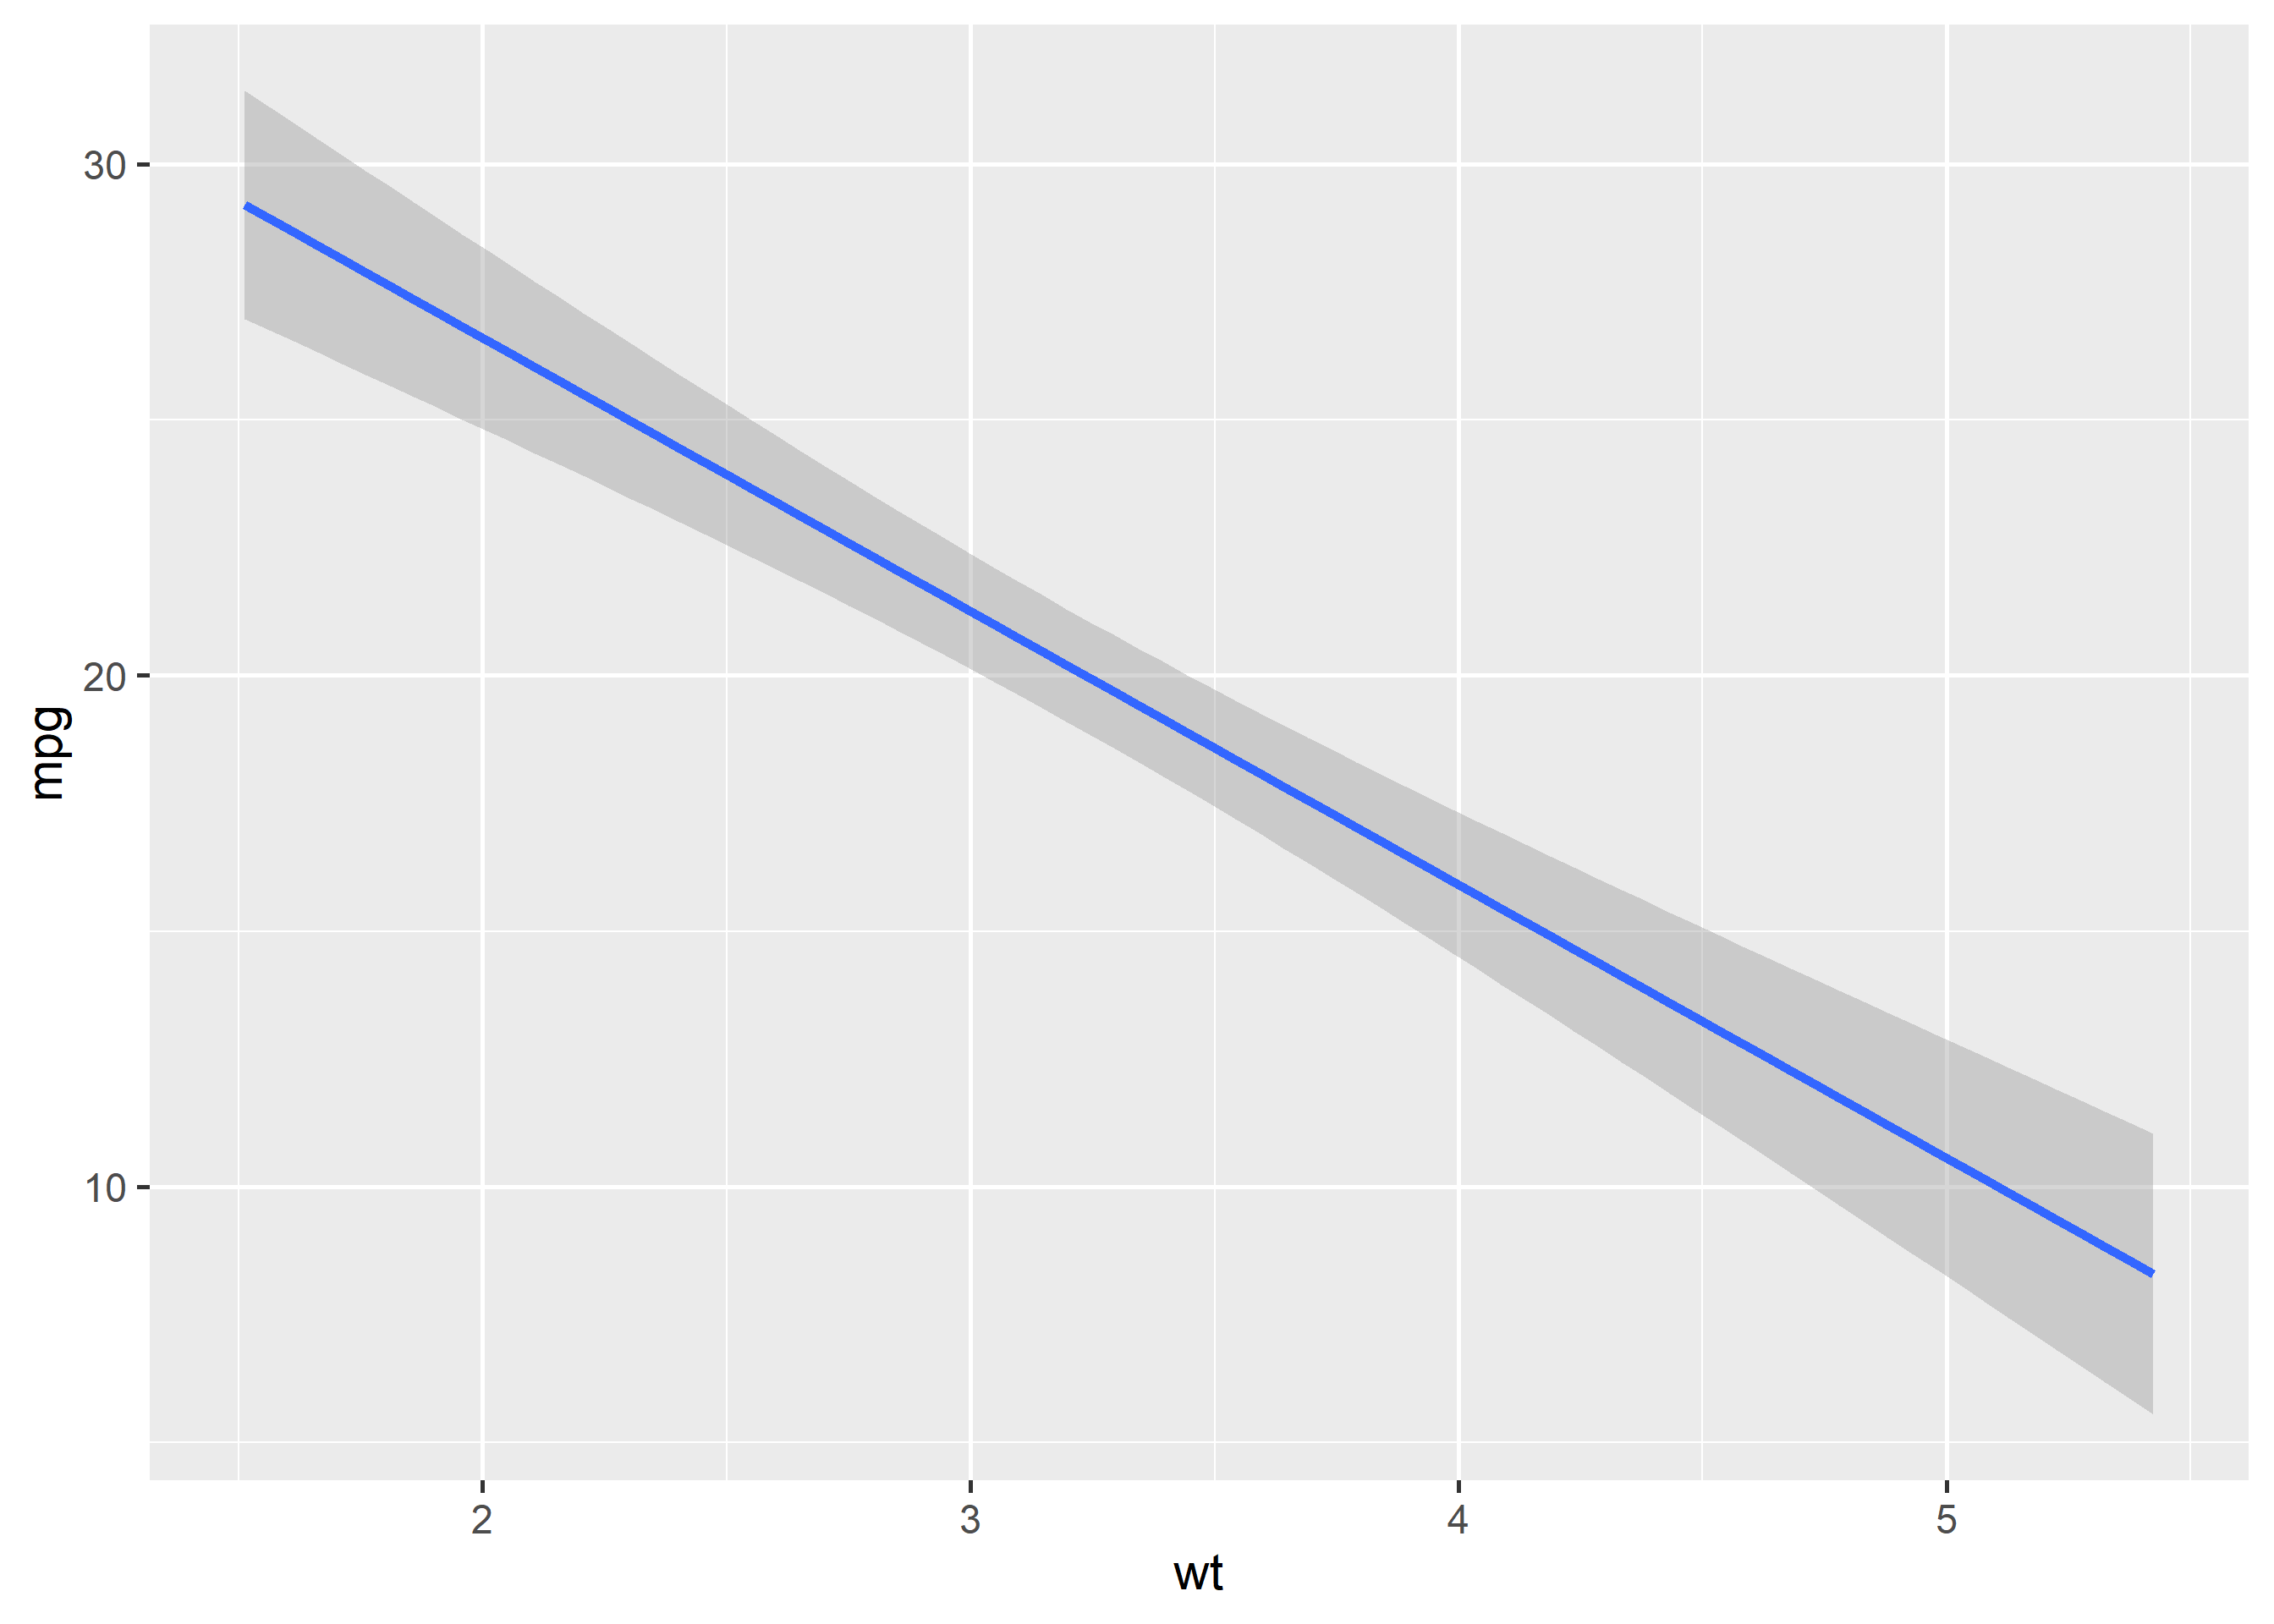
If you are using geom_smooth(), you need to specify the method of fitting the line, which can be lm or loess. You also need to indicate whether the confidence interval must be displayed using the se argument.
ggplot(mtcars, aes(x = wt, y = mpg)) +geom_smooth(method ='lm', formula = y ~ x, se =TRUE)
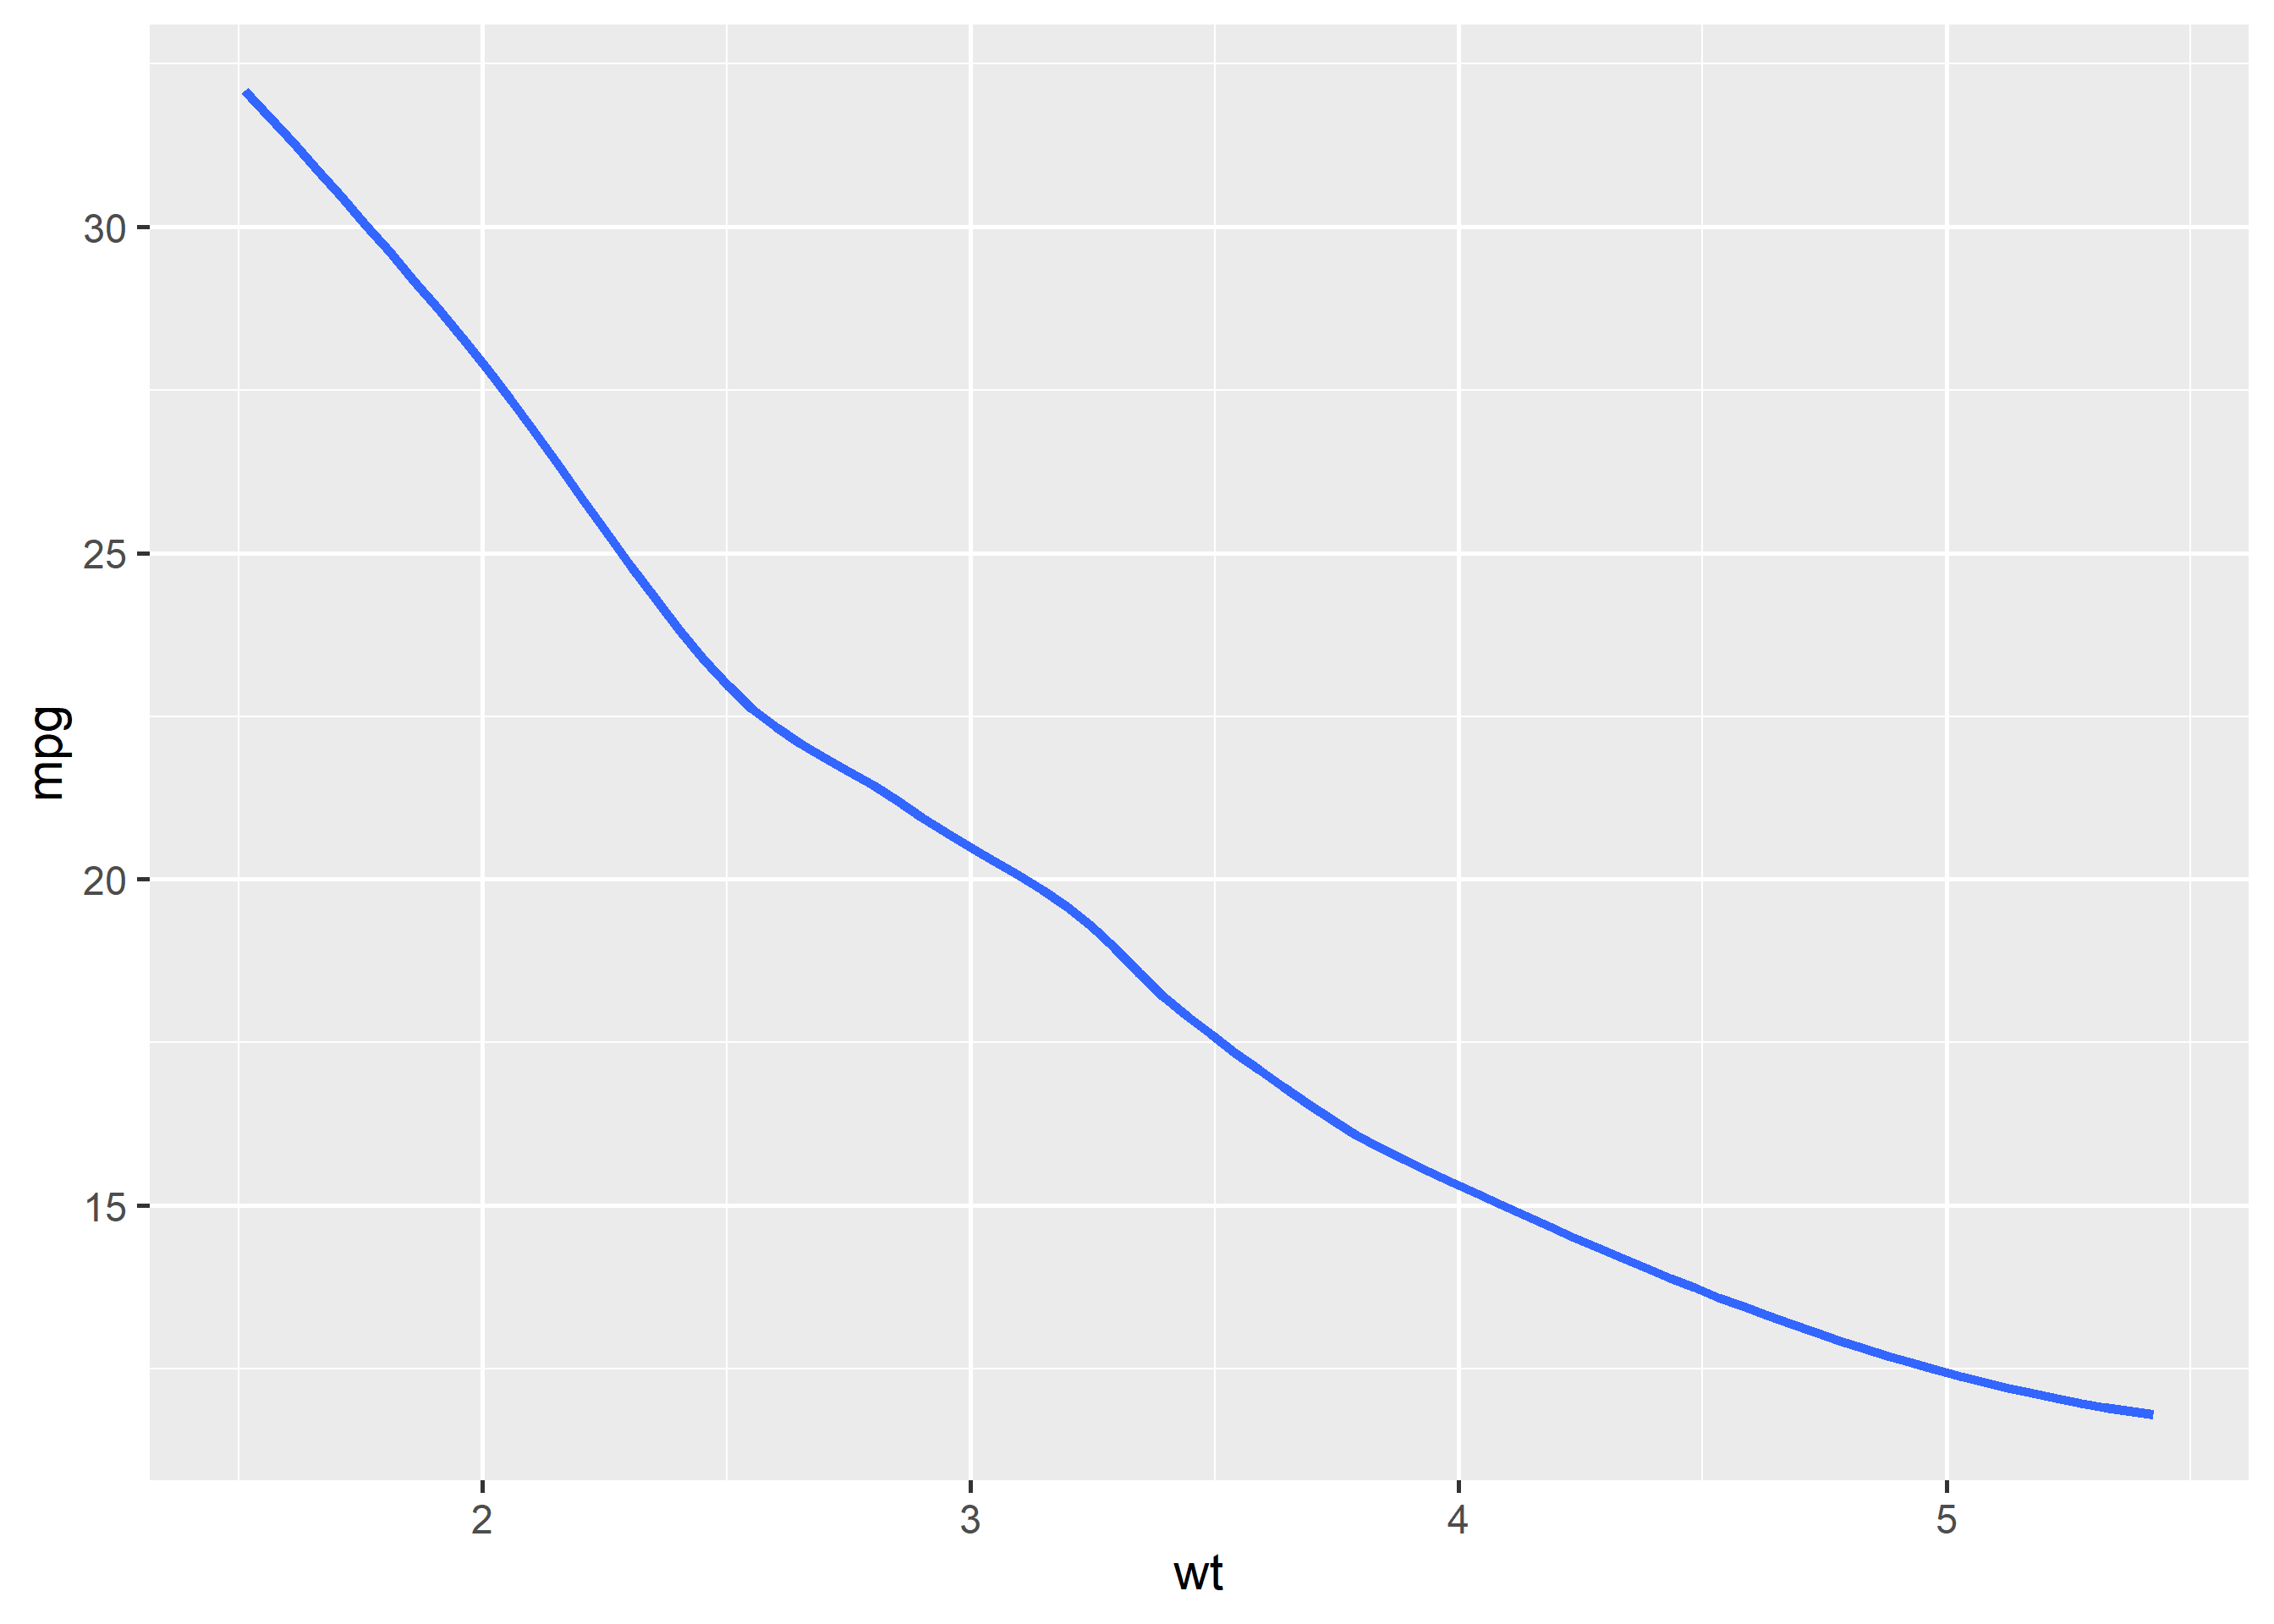
Here we use the 'loess' method to fit the regression line.
ggplot(mtcars, aes(x = wt, y = mpg)) +geom_smooth(method ='loess', formula = y ~ x, se =FALSE)
2.5 Bar
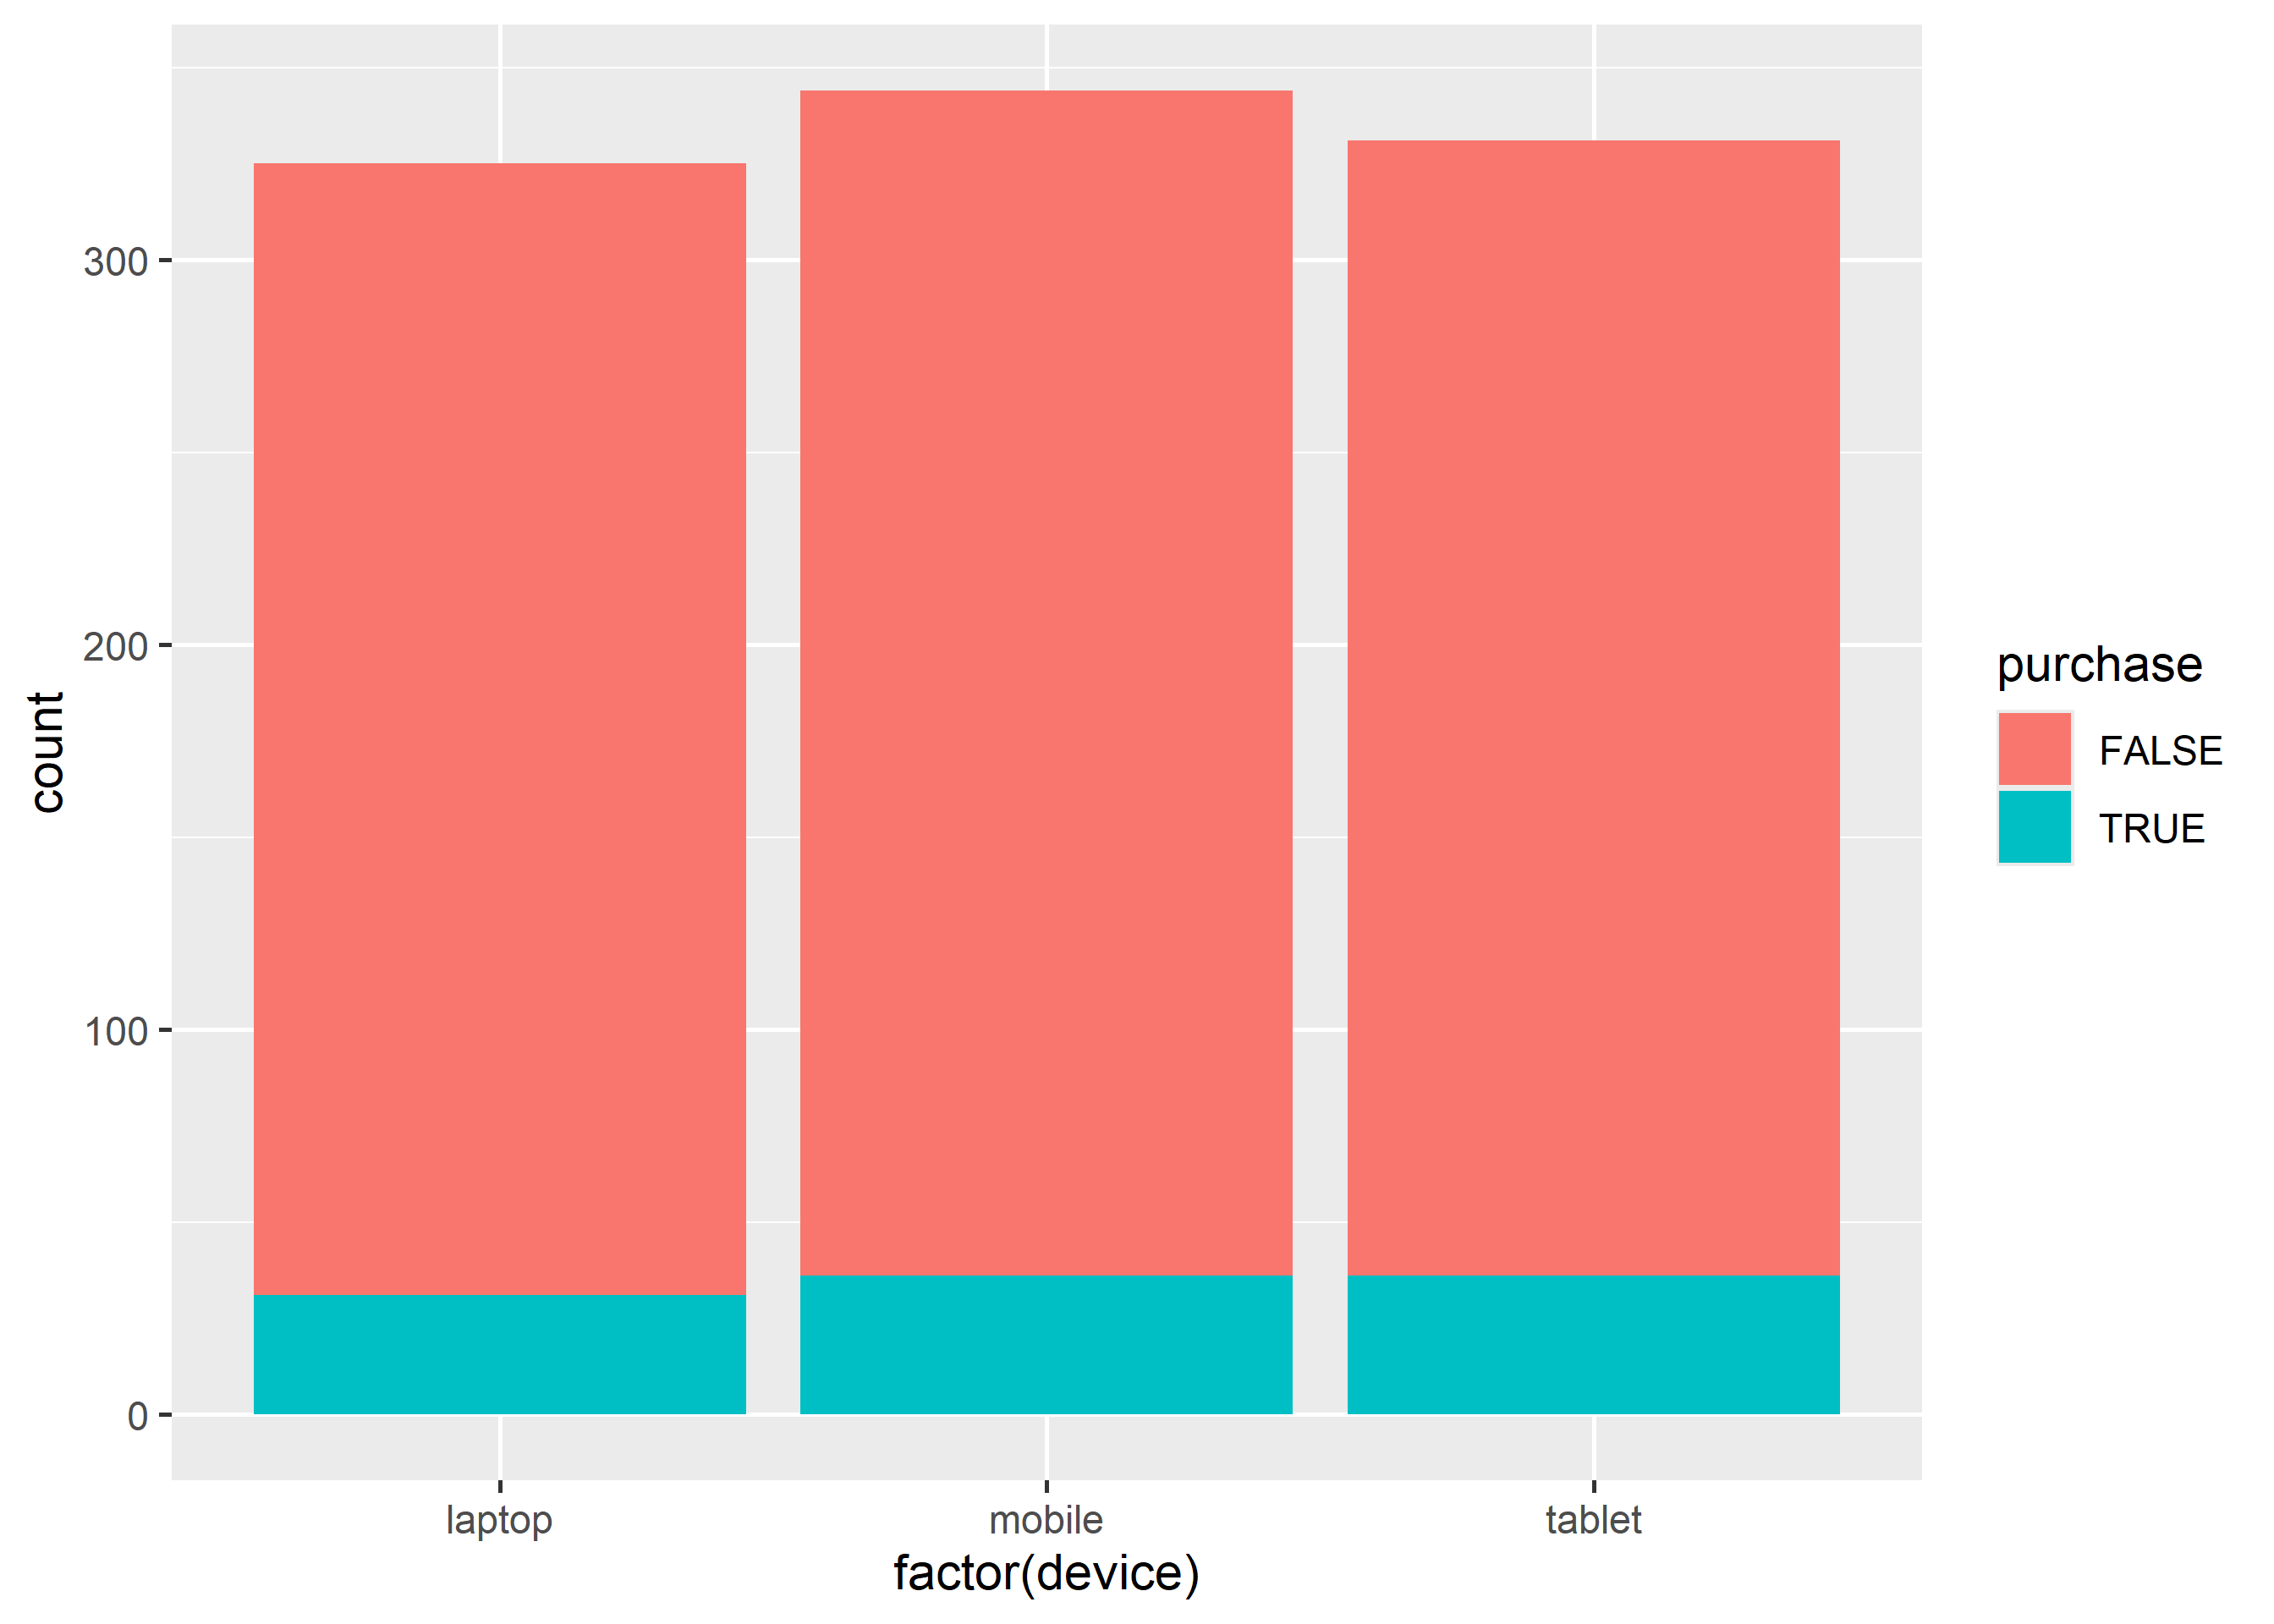
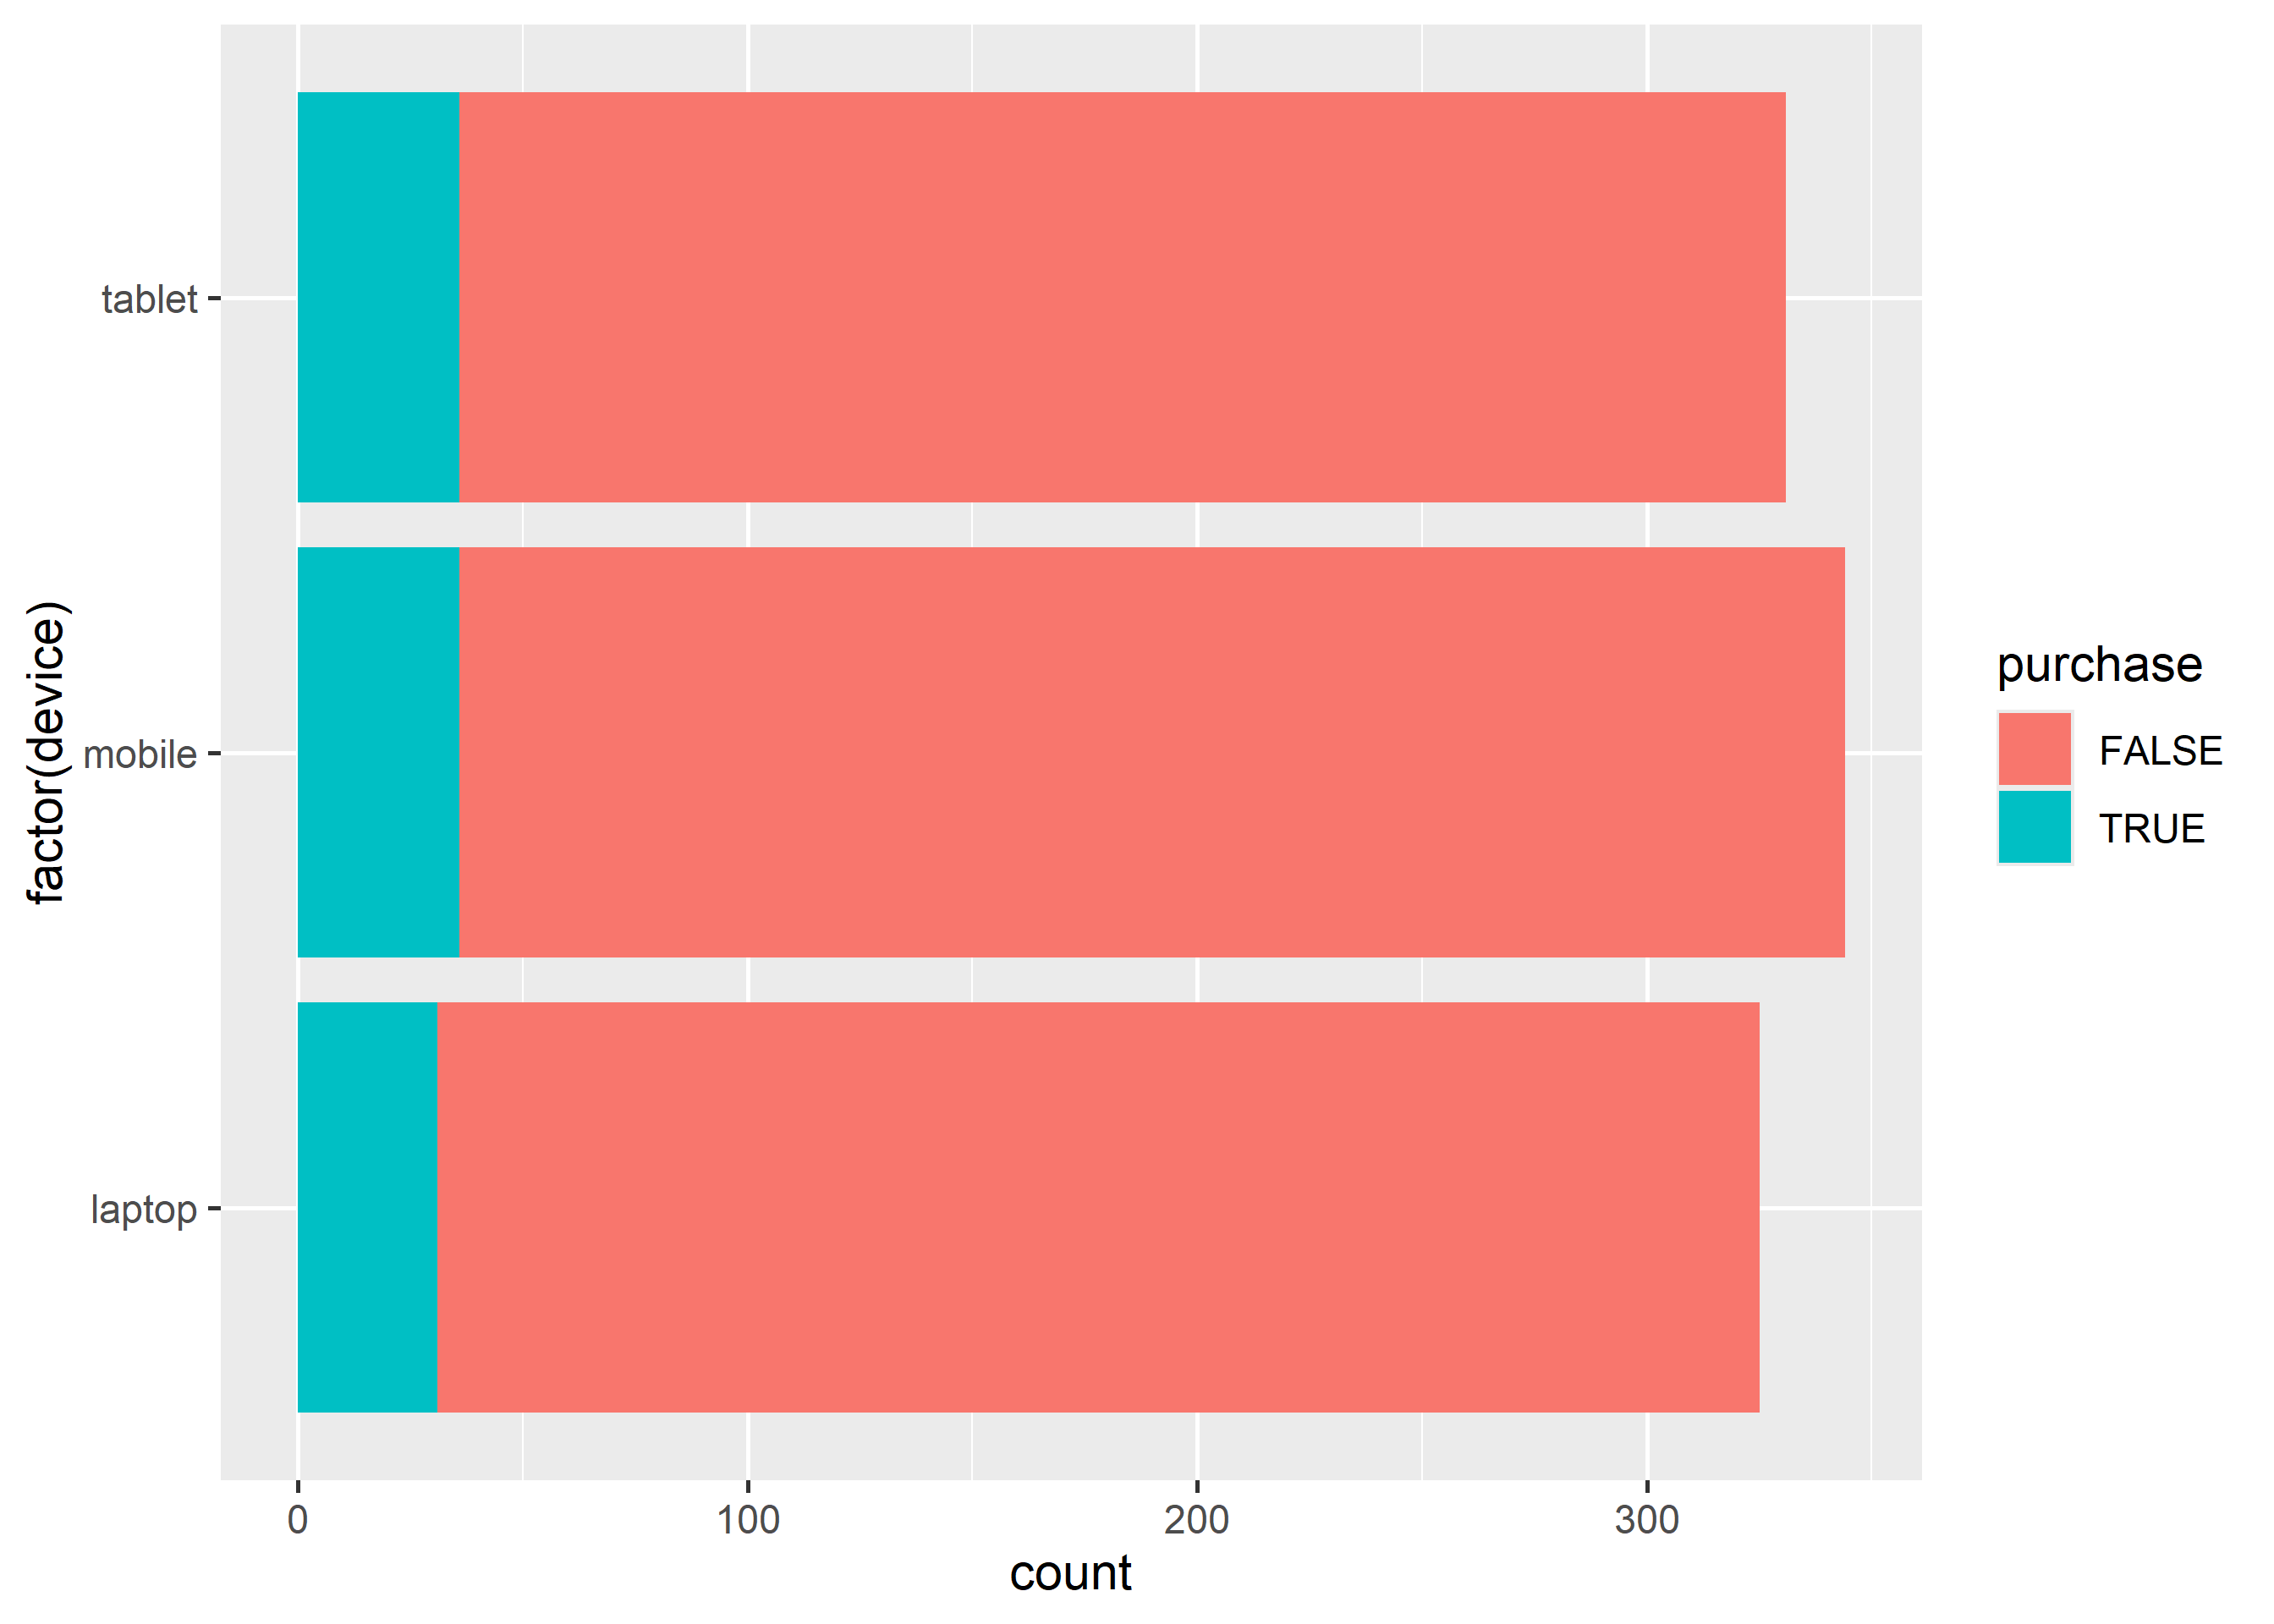
Bar plots present grouped data with rectangular bars. The bars may represent the frequency of the groups or values. Bar plots can be:
horizontal
vertical
grouped
stacked
proportional
2.5.1 Frequency
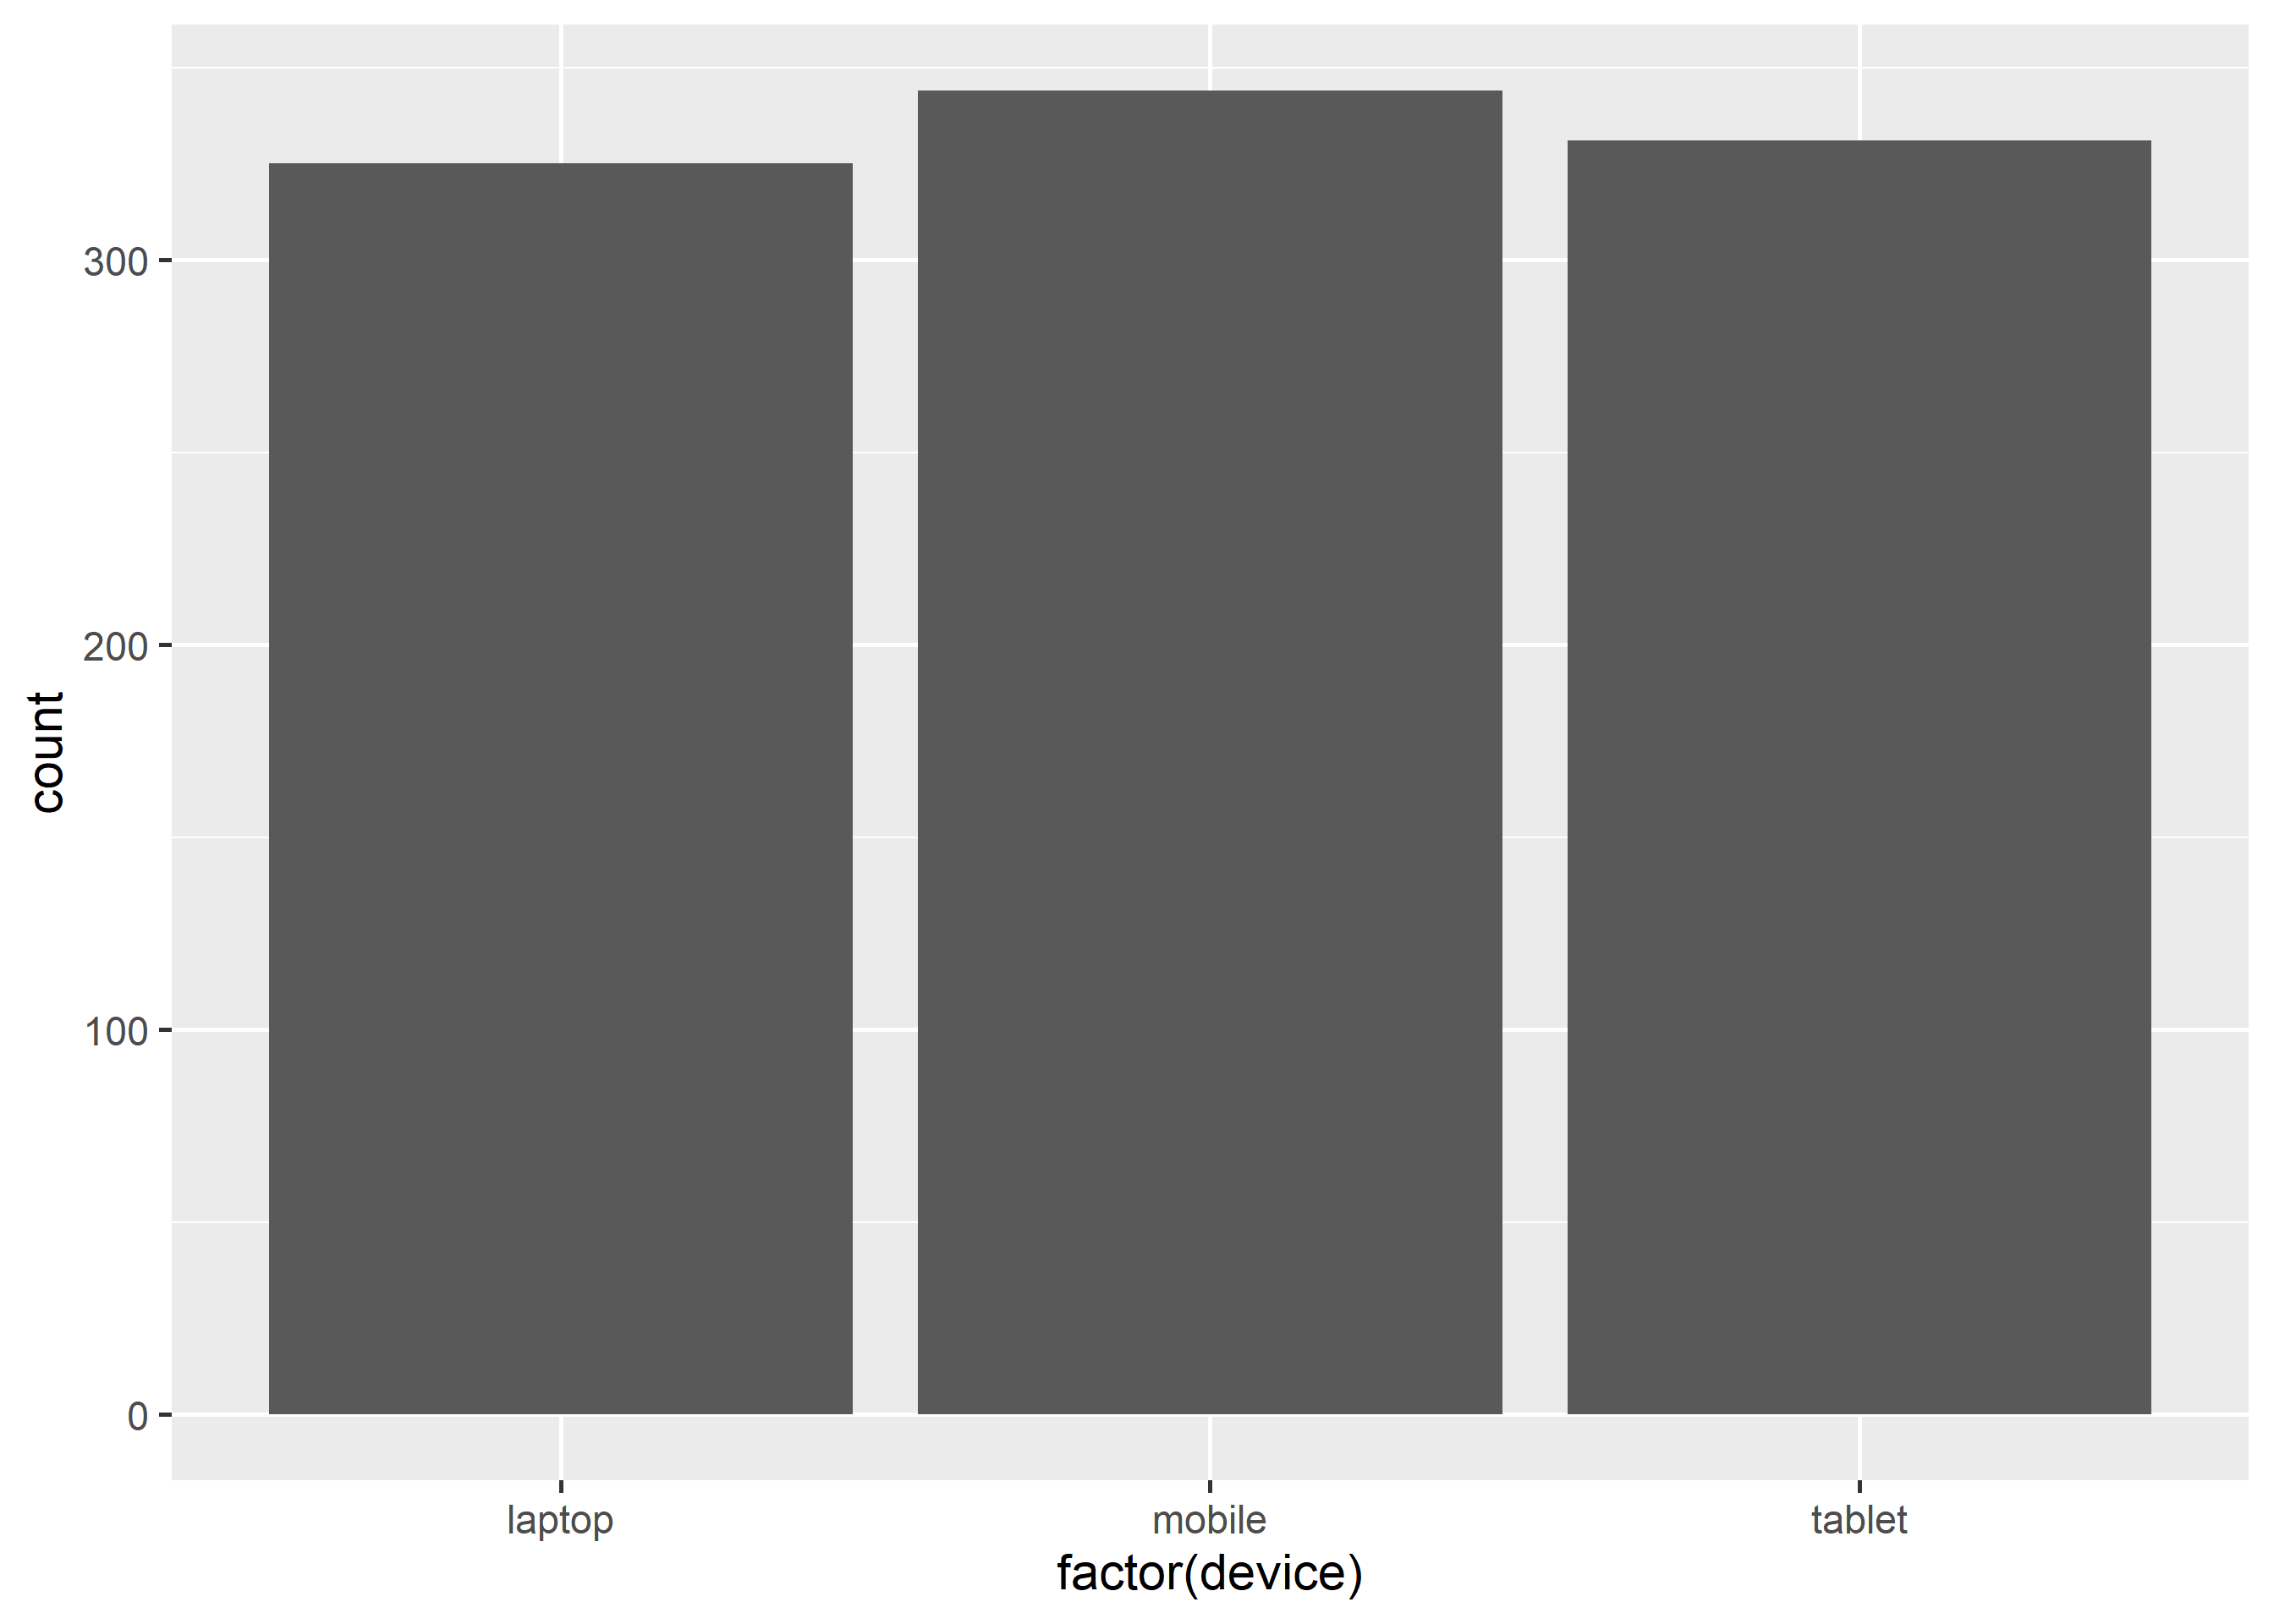
ggplot(ecom, aes(x =factor(device))) +geom_bar()
2.5.2 Weight
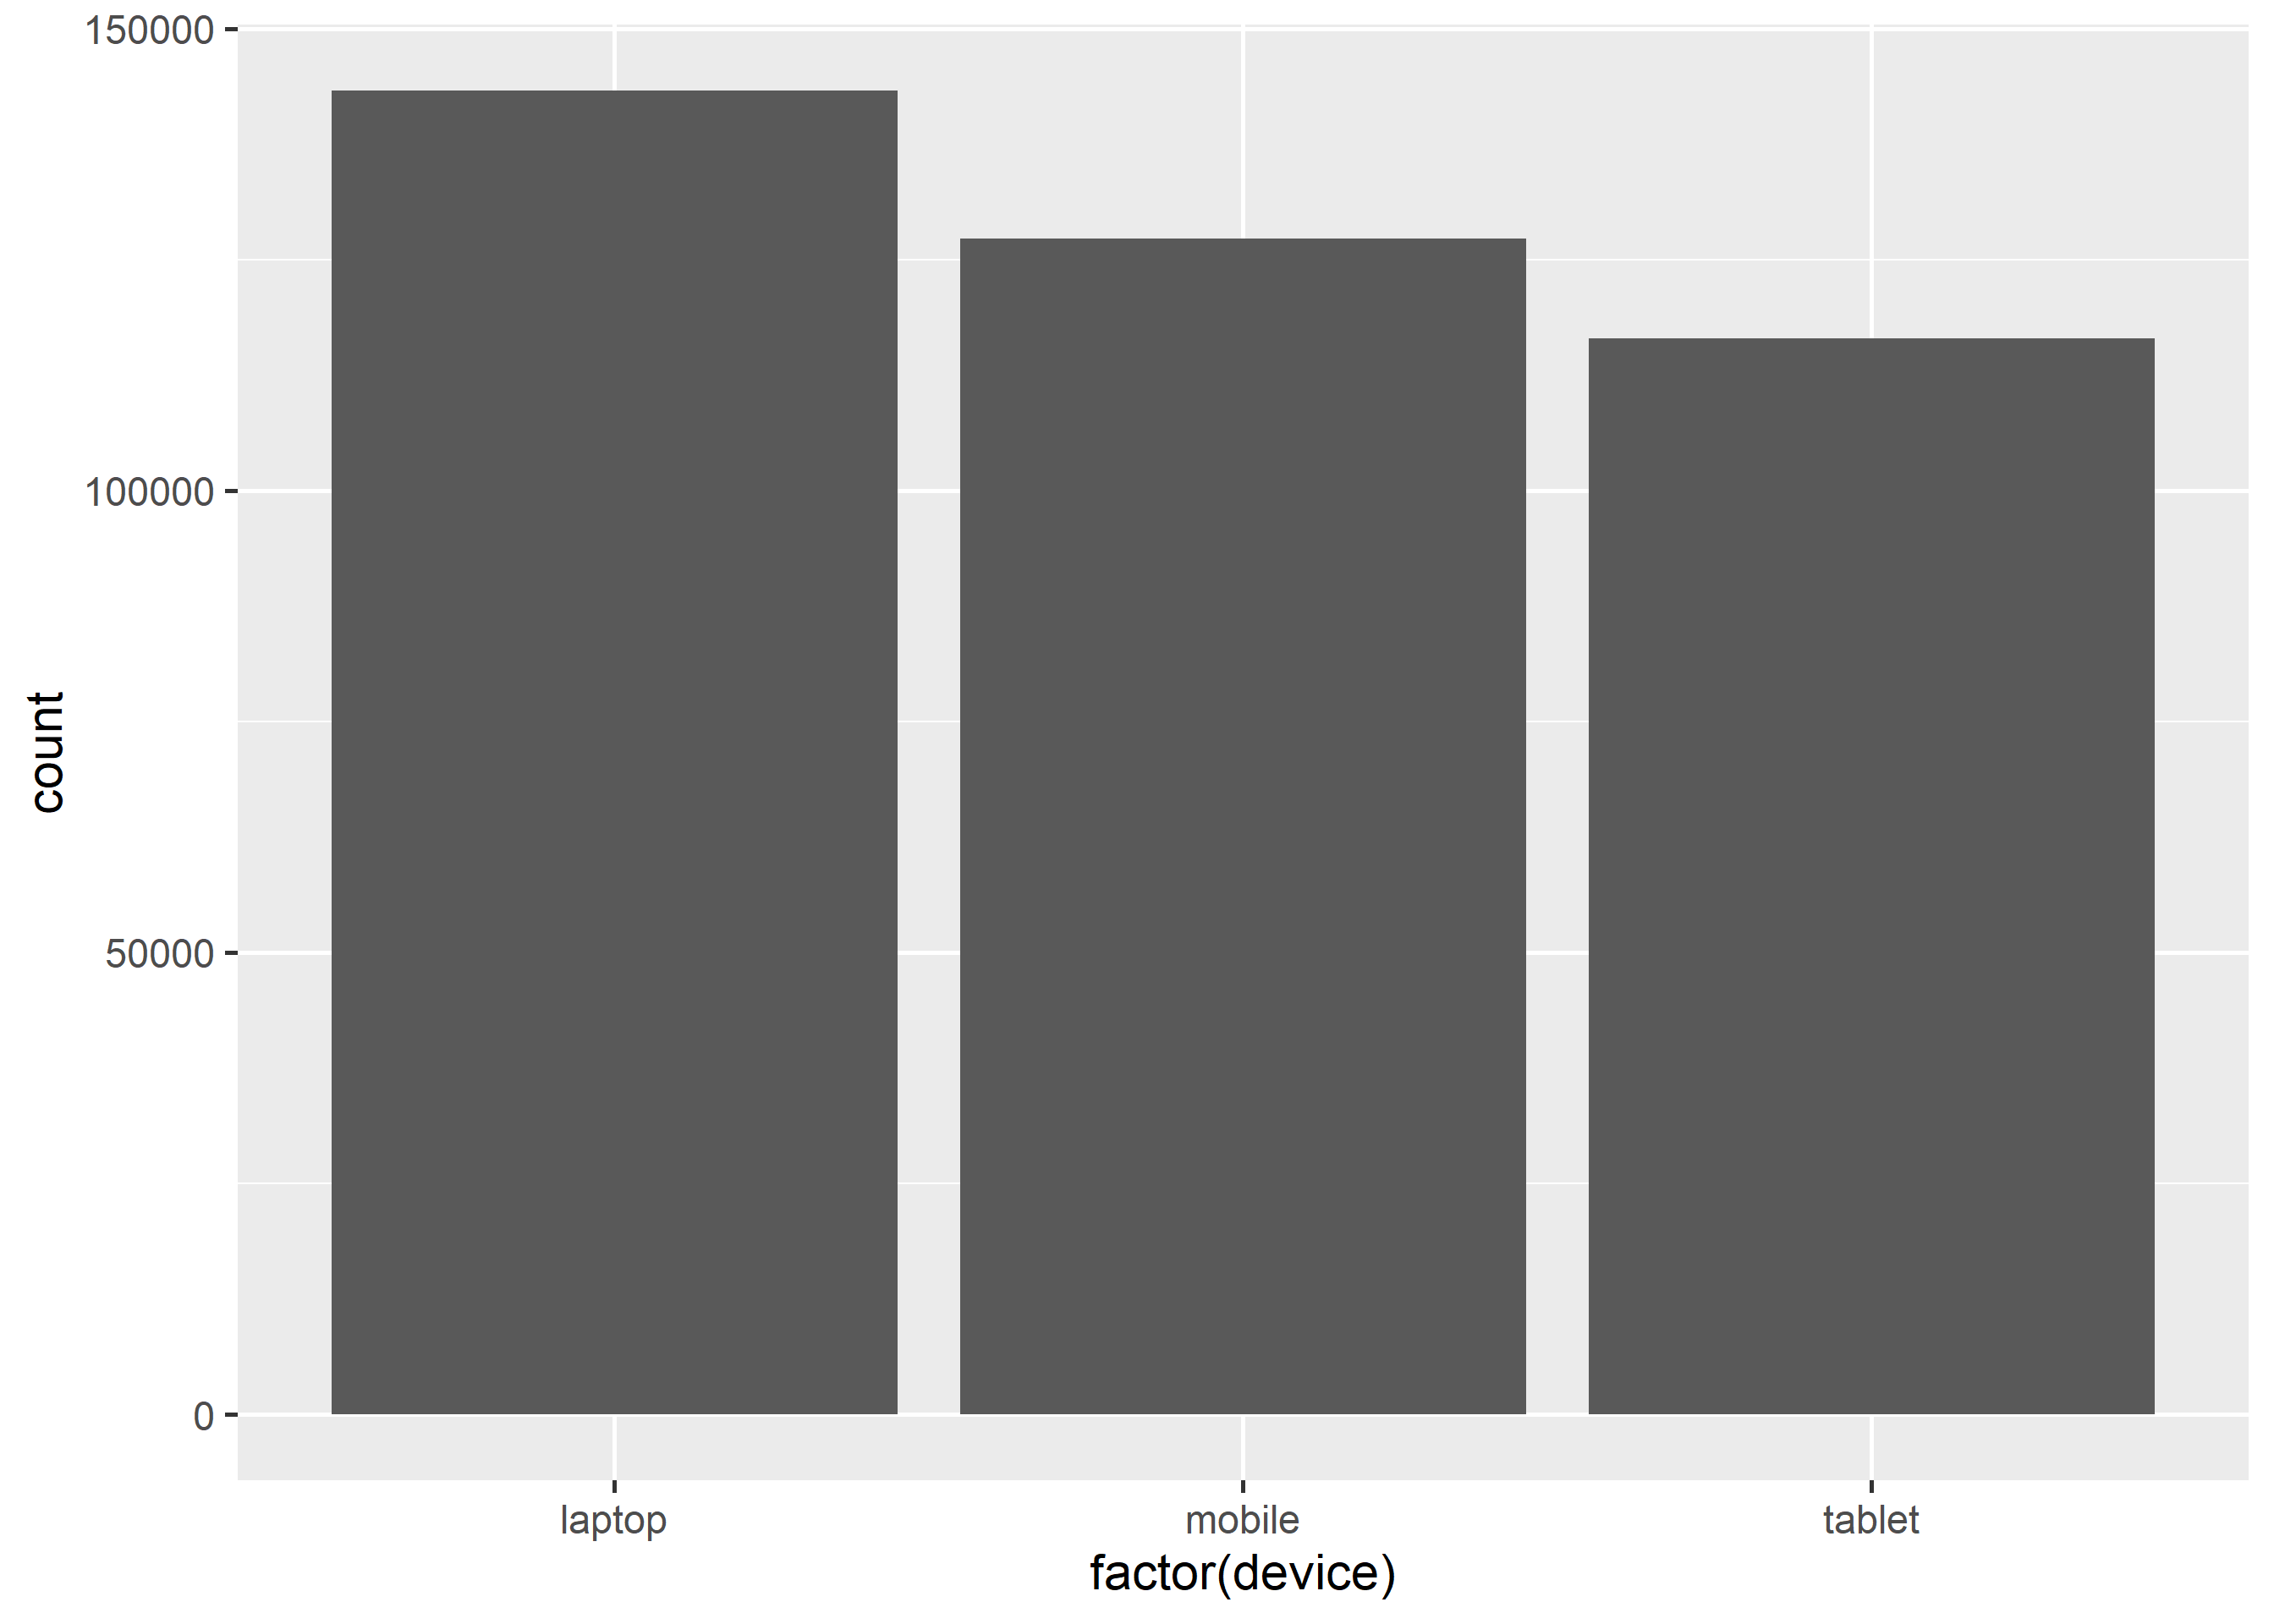
If the bars should represent a continuous variable, use the weight argument within aes(). In the below example, the bars do not represent the count of devices, instead, they represent the total order value for each device type.
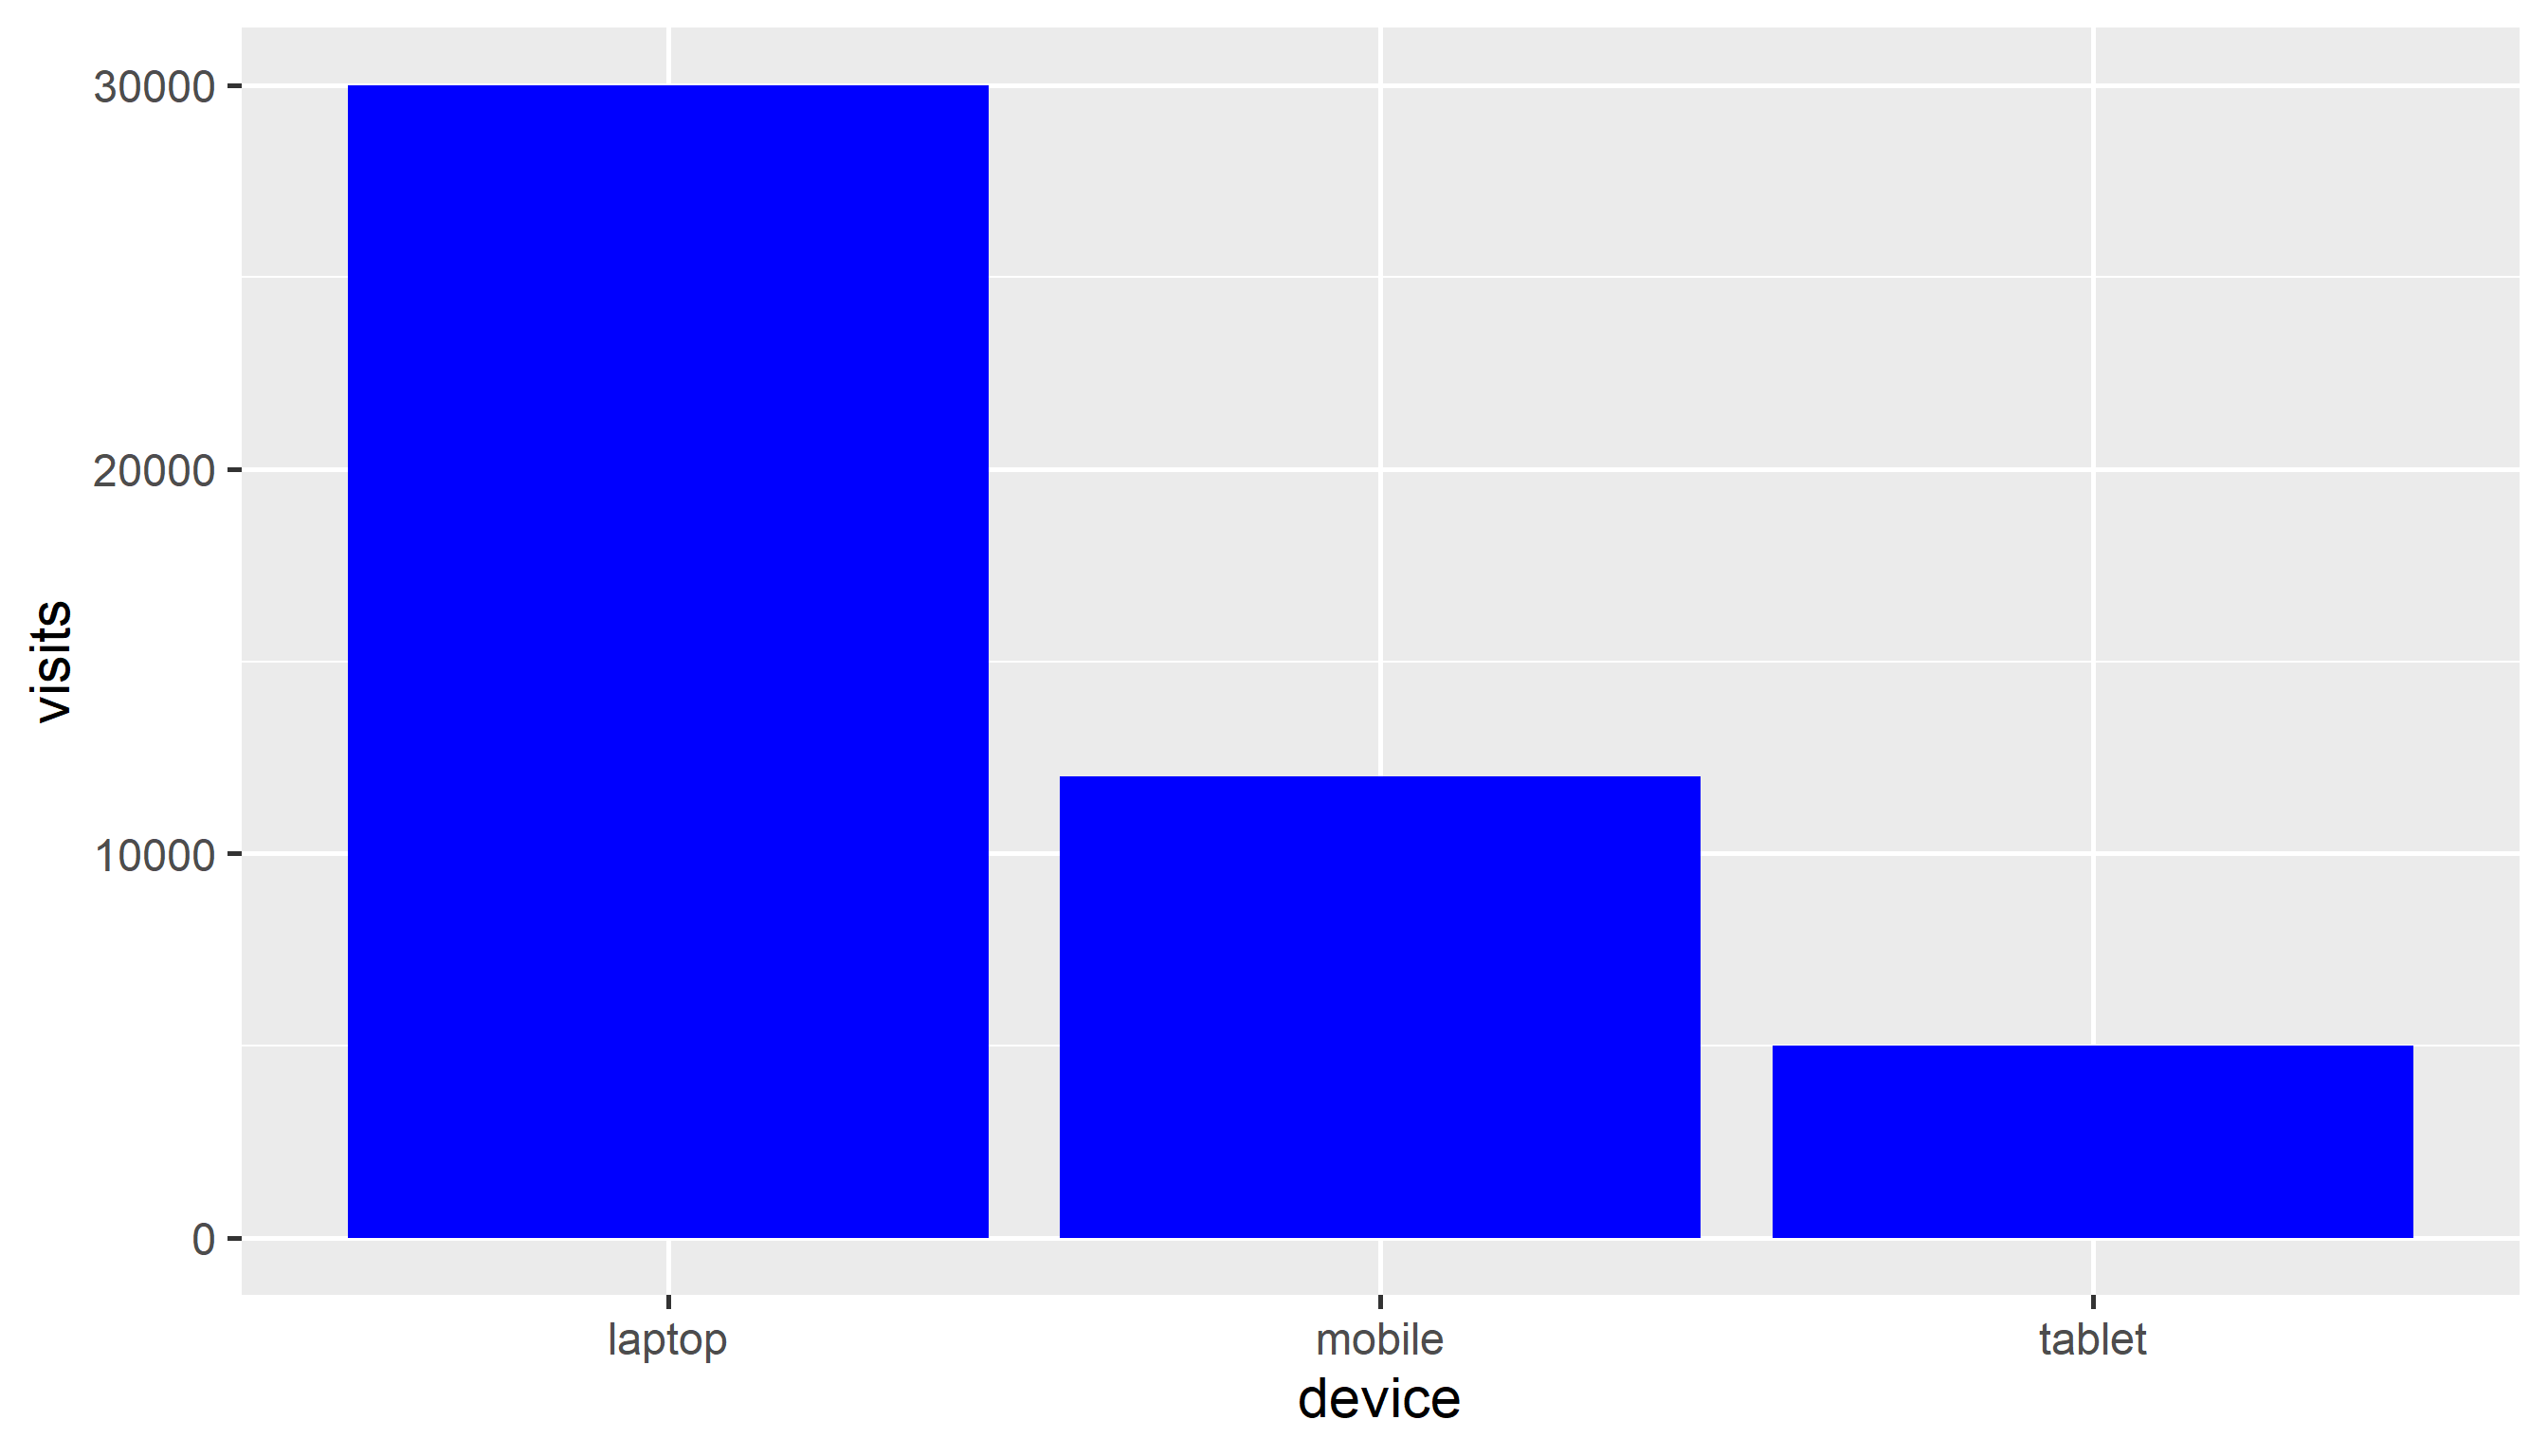
If the data has already been summarized, you can use geom_col() instead of geom_bar(). In the below example, we have the total visits for each device type. The data has already been summarized and as such we cannot use geom_bar().
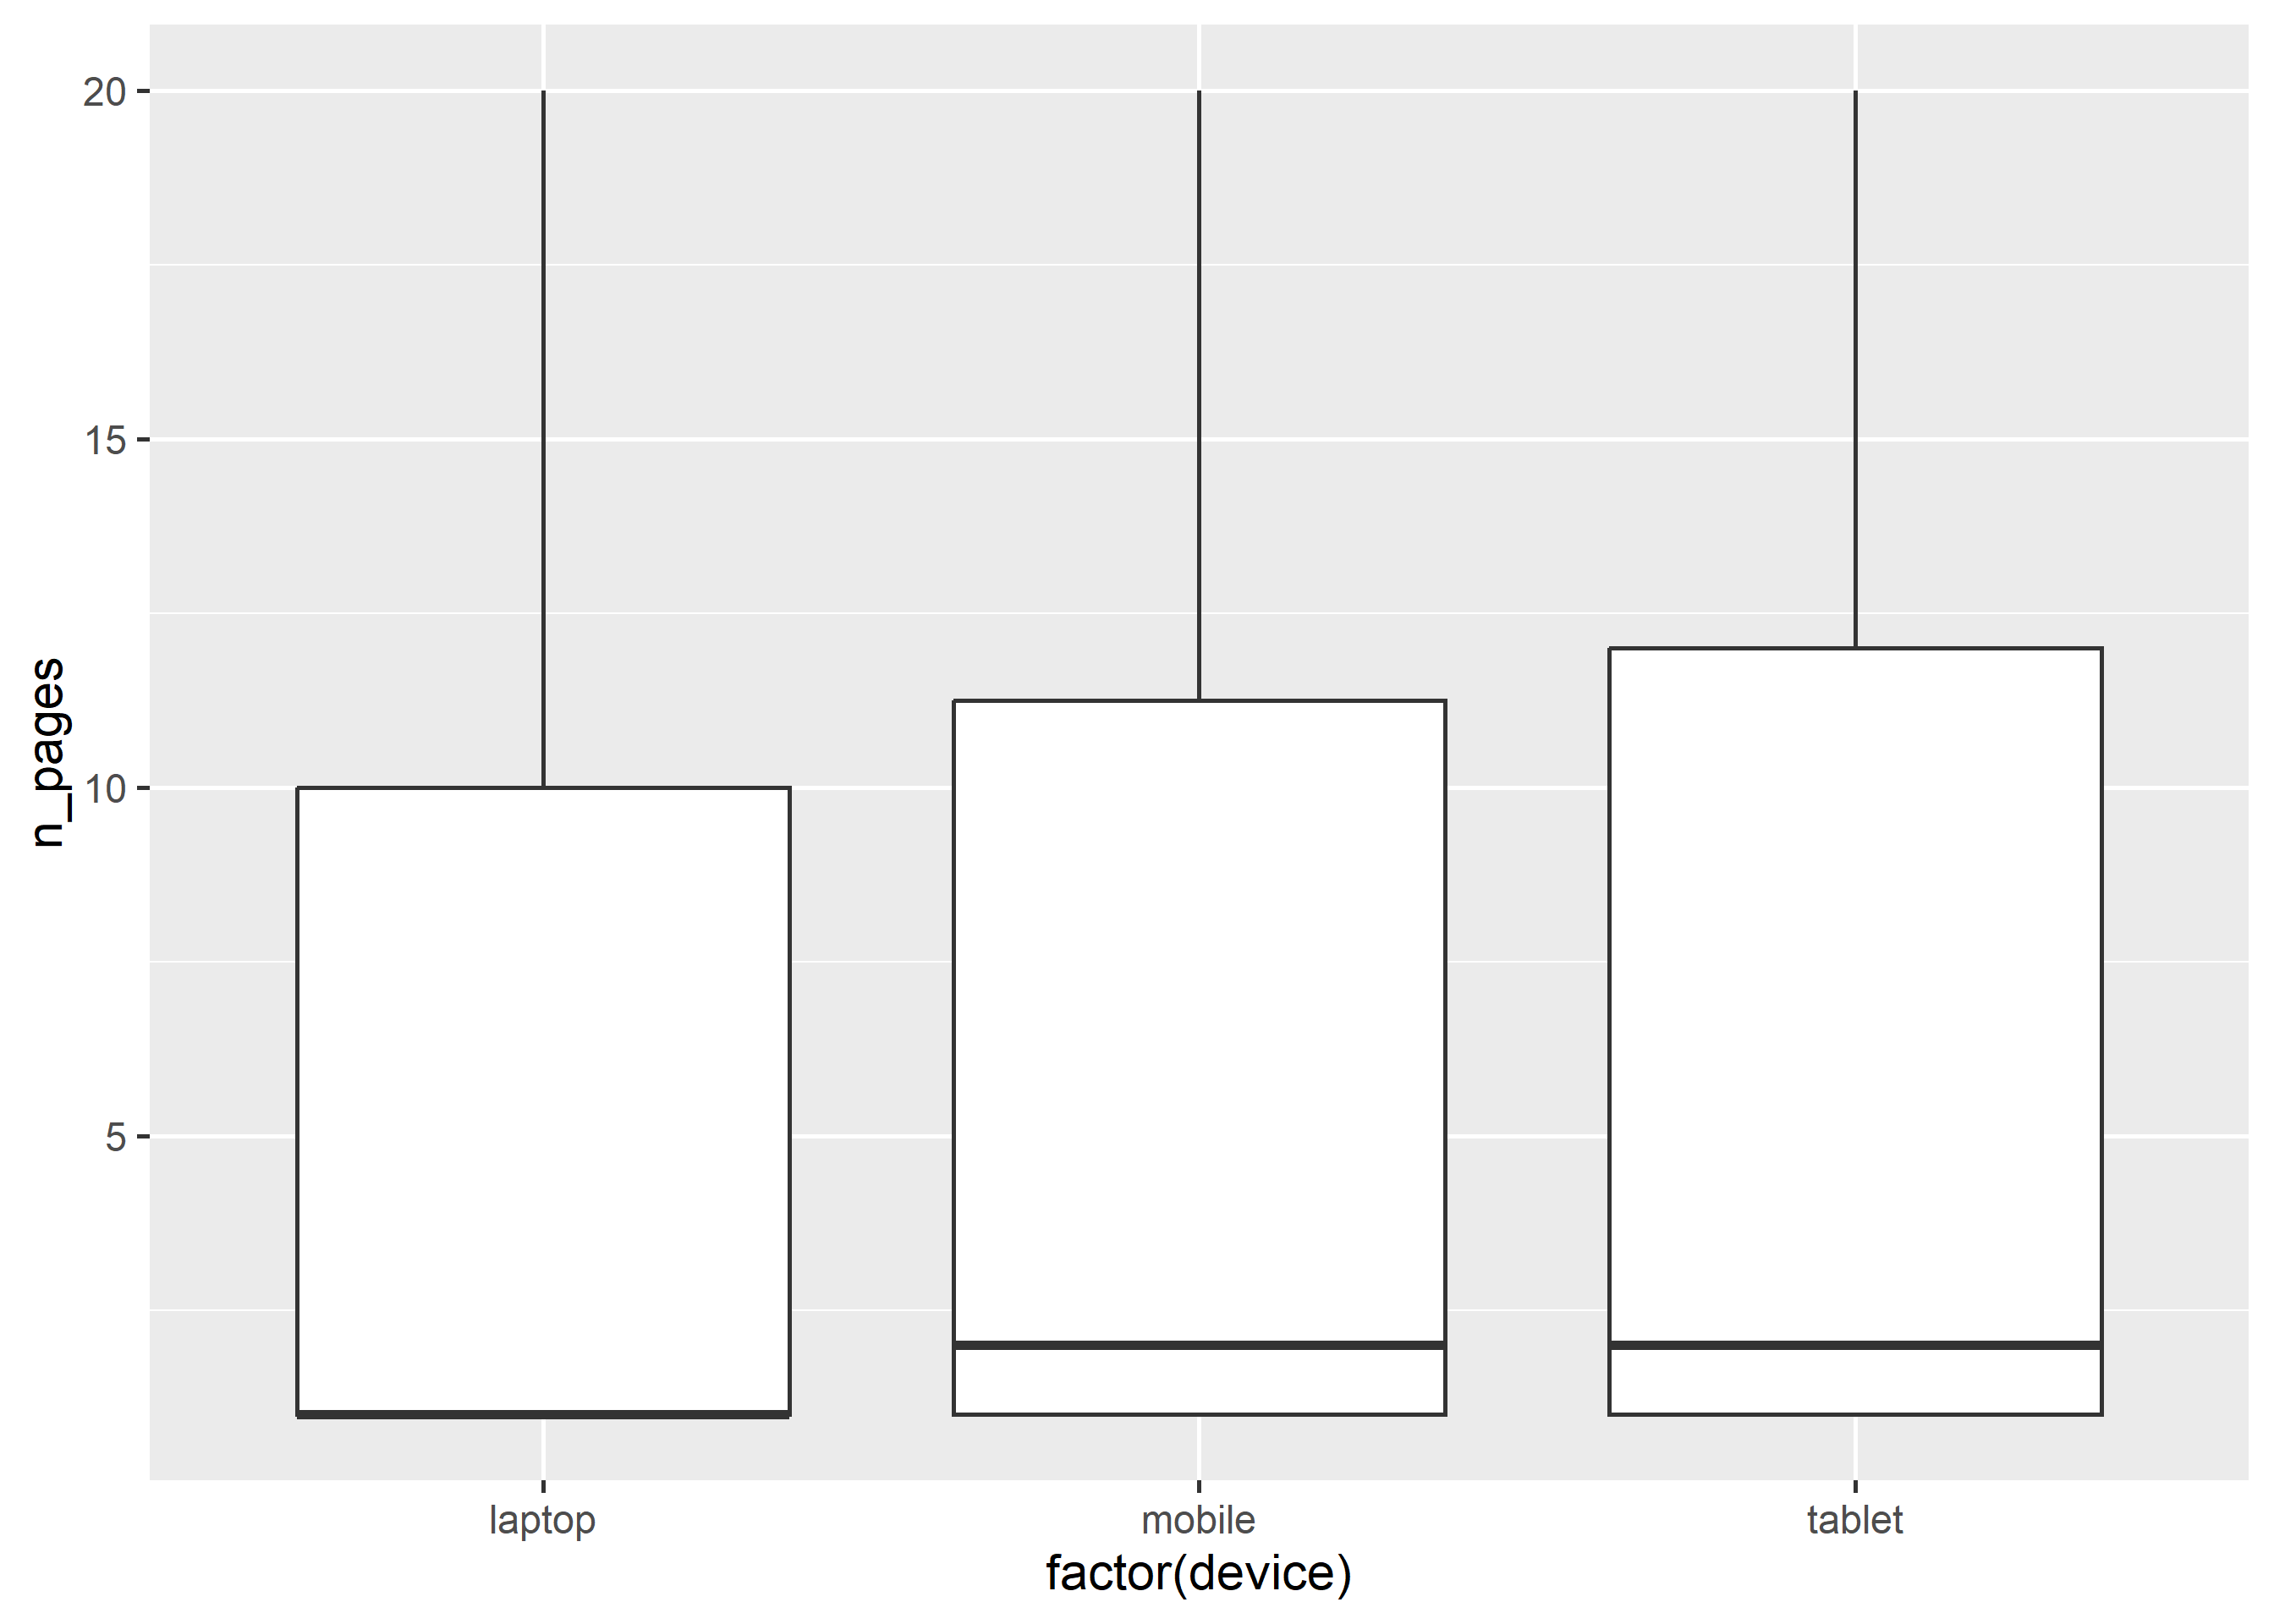
The box plot is a standardized way of displaying the distribution of data based on the five number summary: minimum, first quartile, median, third quartile, and maximum. Box plots are useful for detecting outliers and for comparing distributions. It shows the shape, central tendancy and variability of the data. Use geom_boxplot() to create a box plot.
ggplot(ecom, aes(x =factor(device), y = n_pages)) +geom_boxplot()
2.8 Histogram
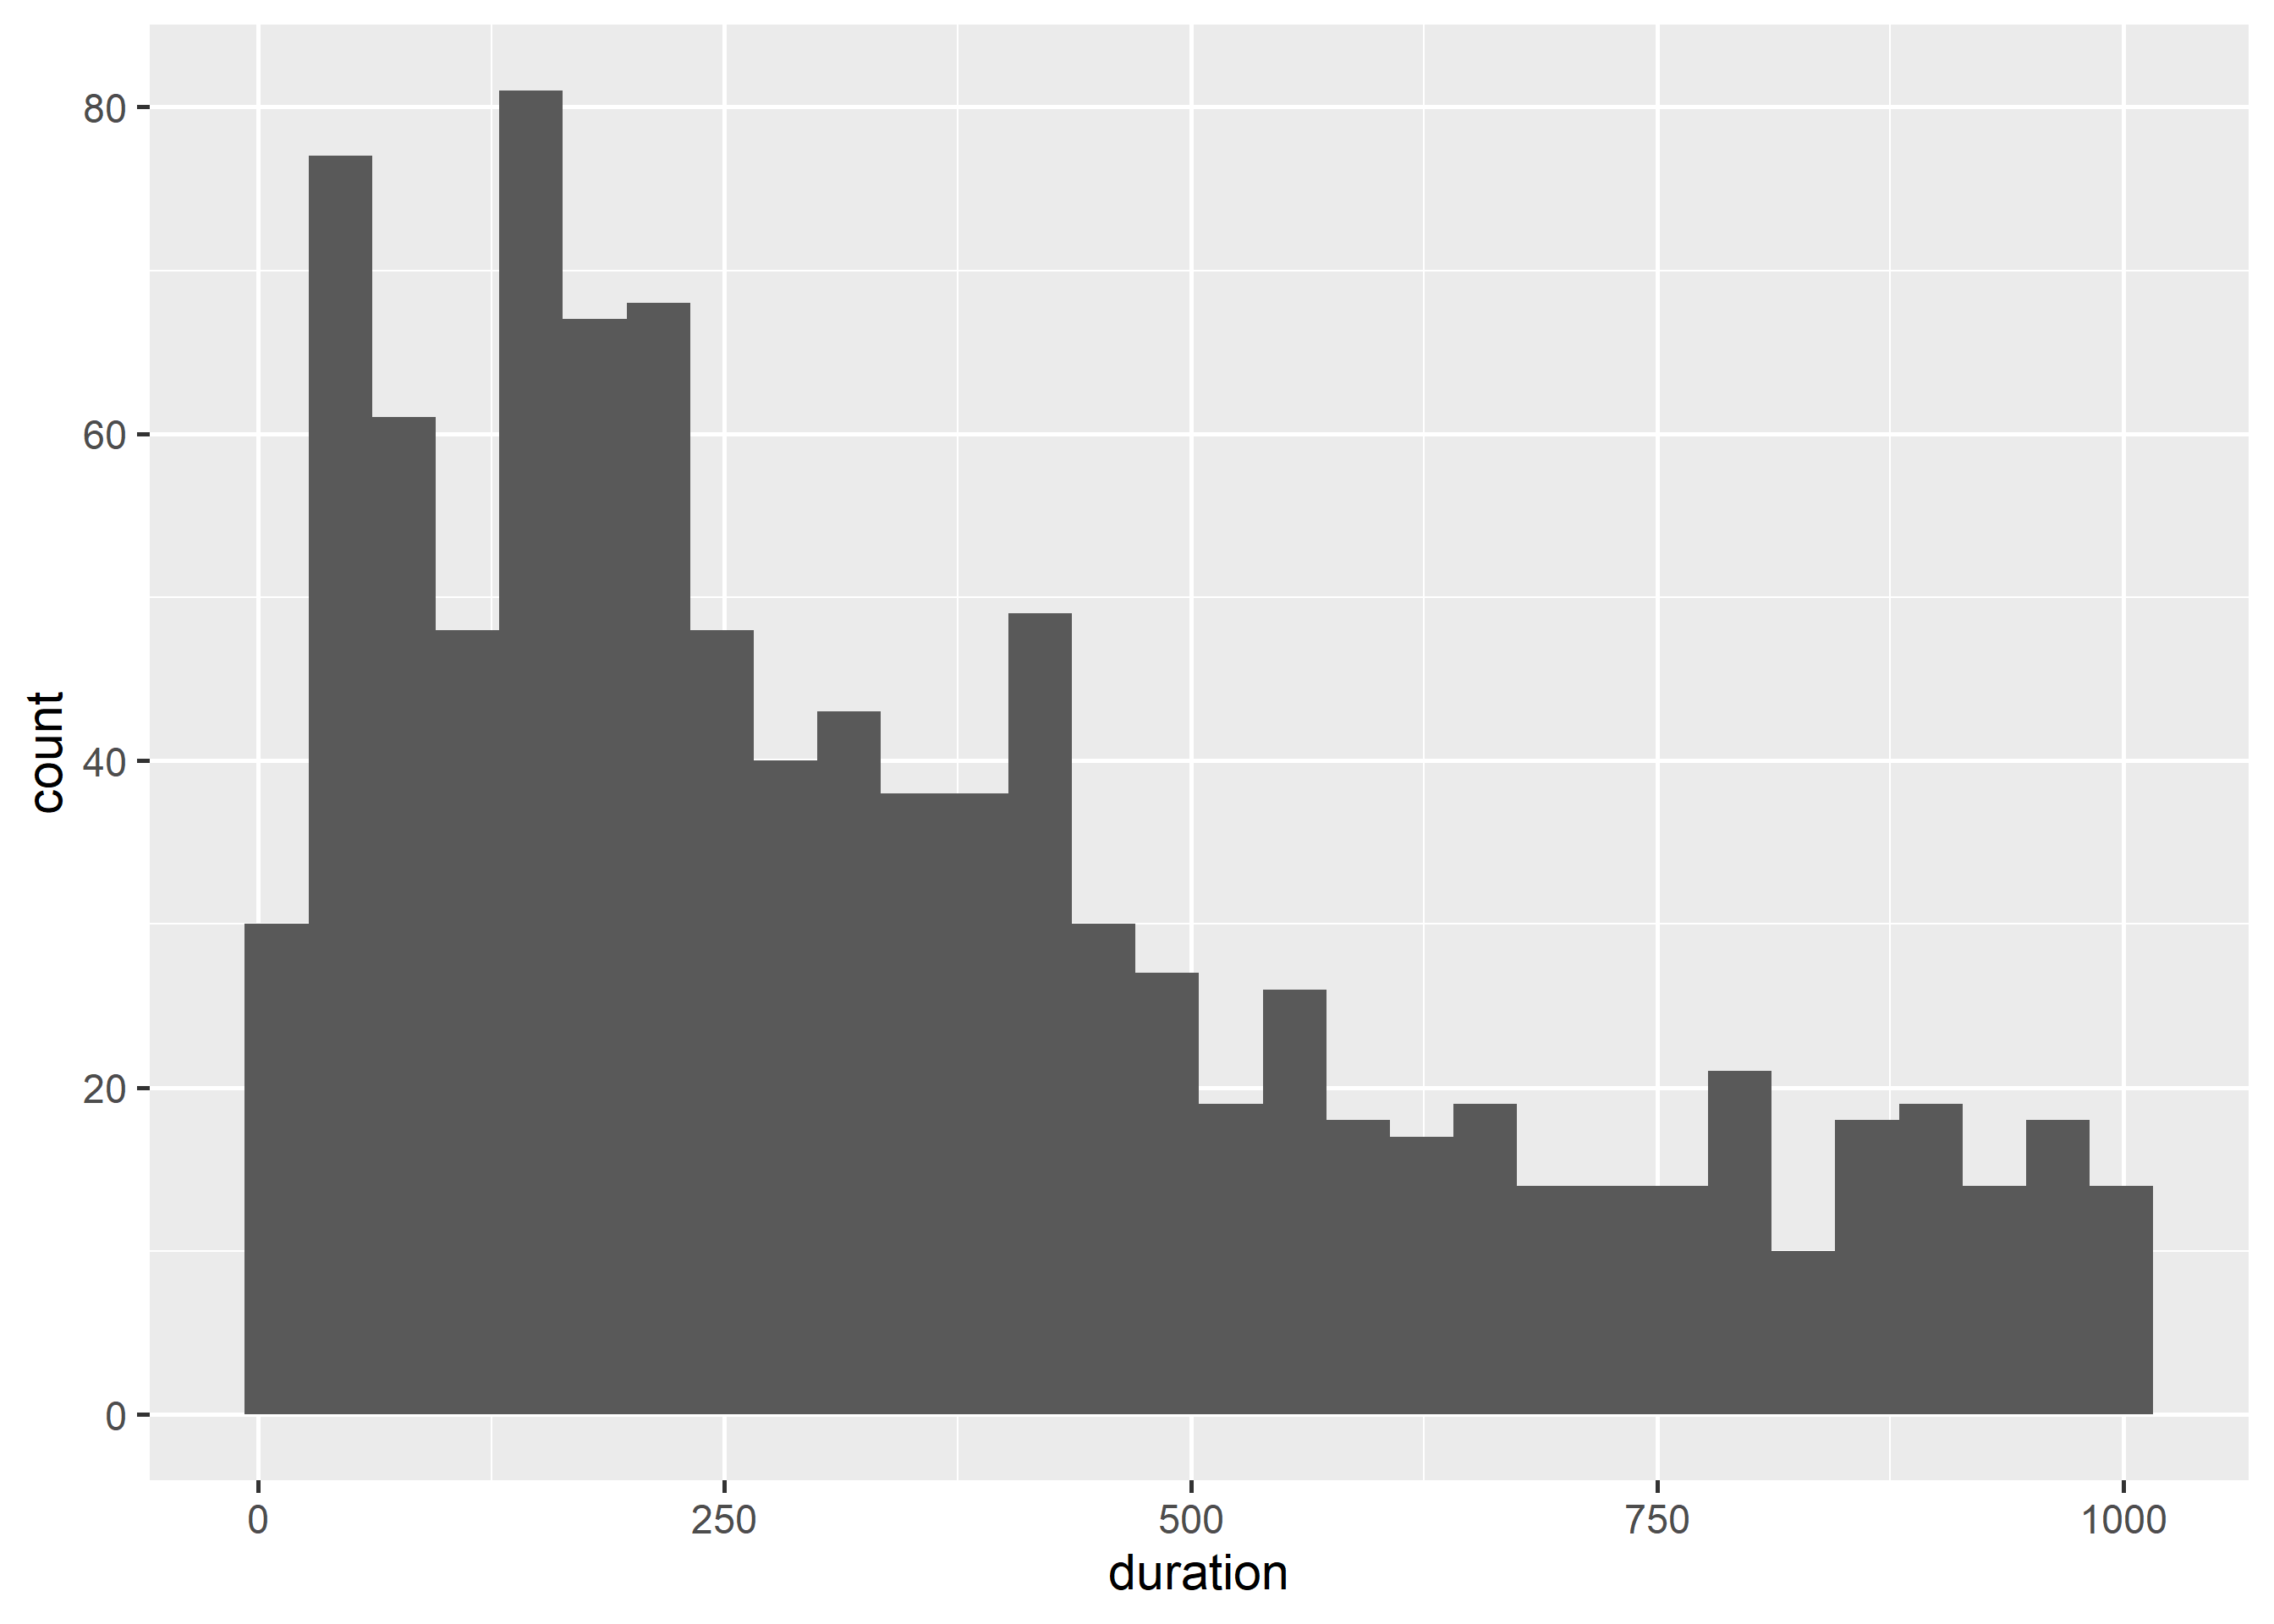
A histogram is a plot that can be used to examine the shape and spread of continuous data. It looks very similar to a bar graph and can be used to detect outliers and skewness in data. Use geom_histogram() to create a histogram.
ggplot(ecom, aes(x = duration)) +geom_histogram()
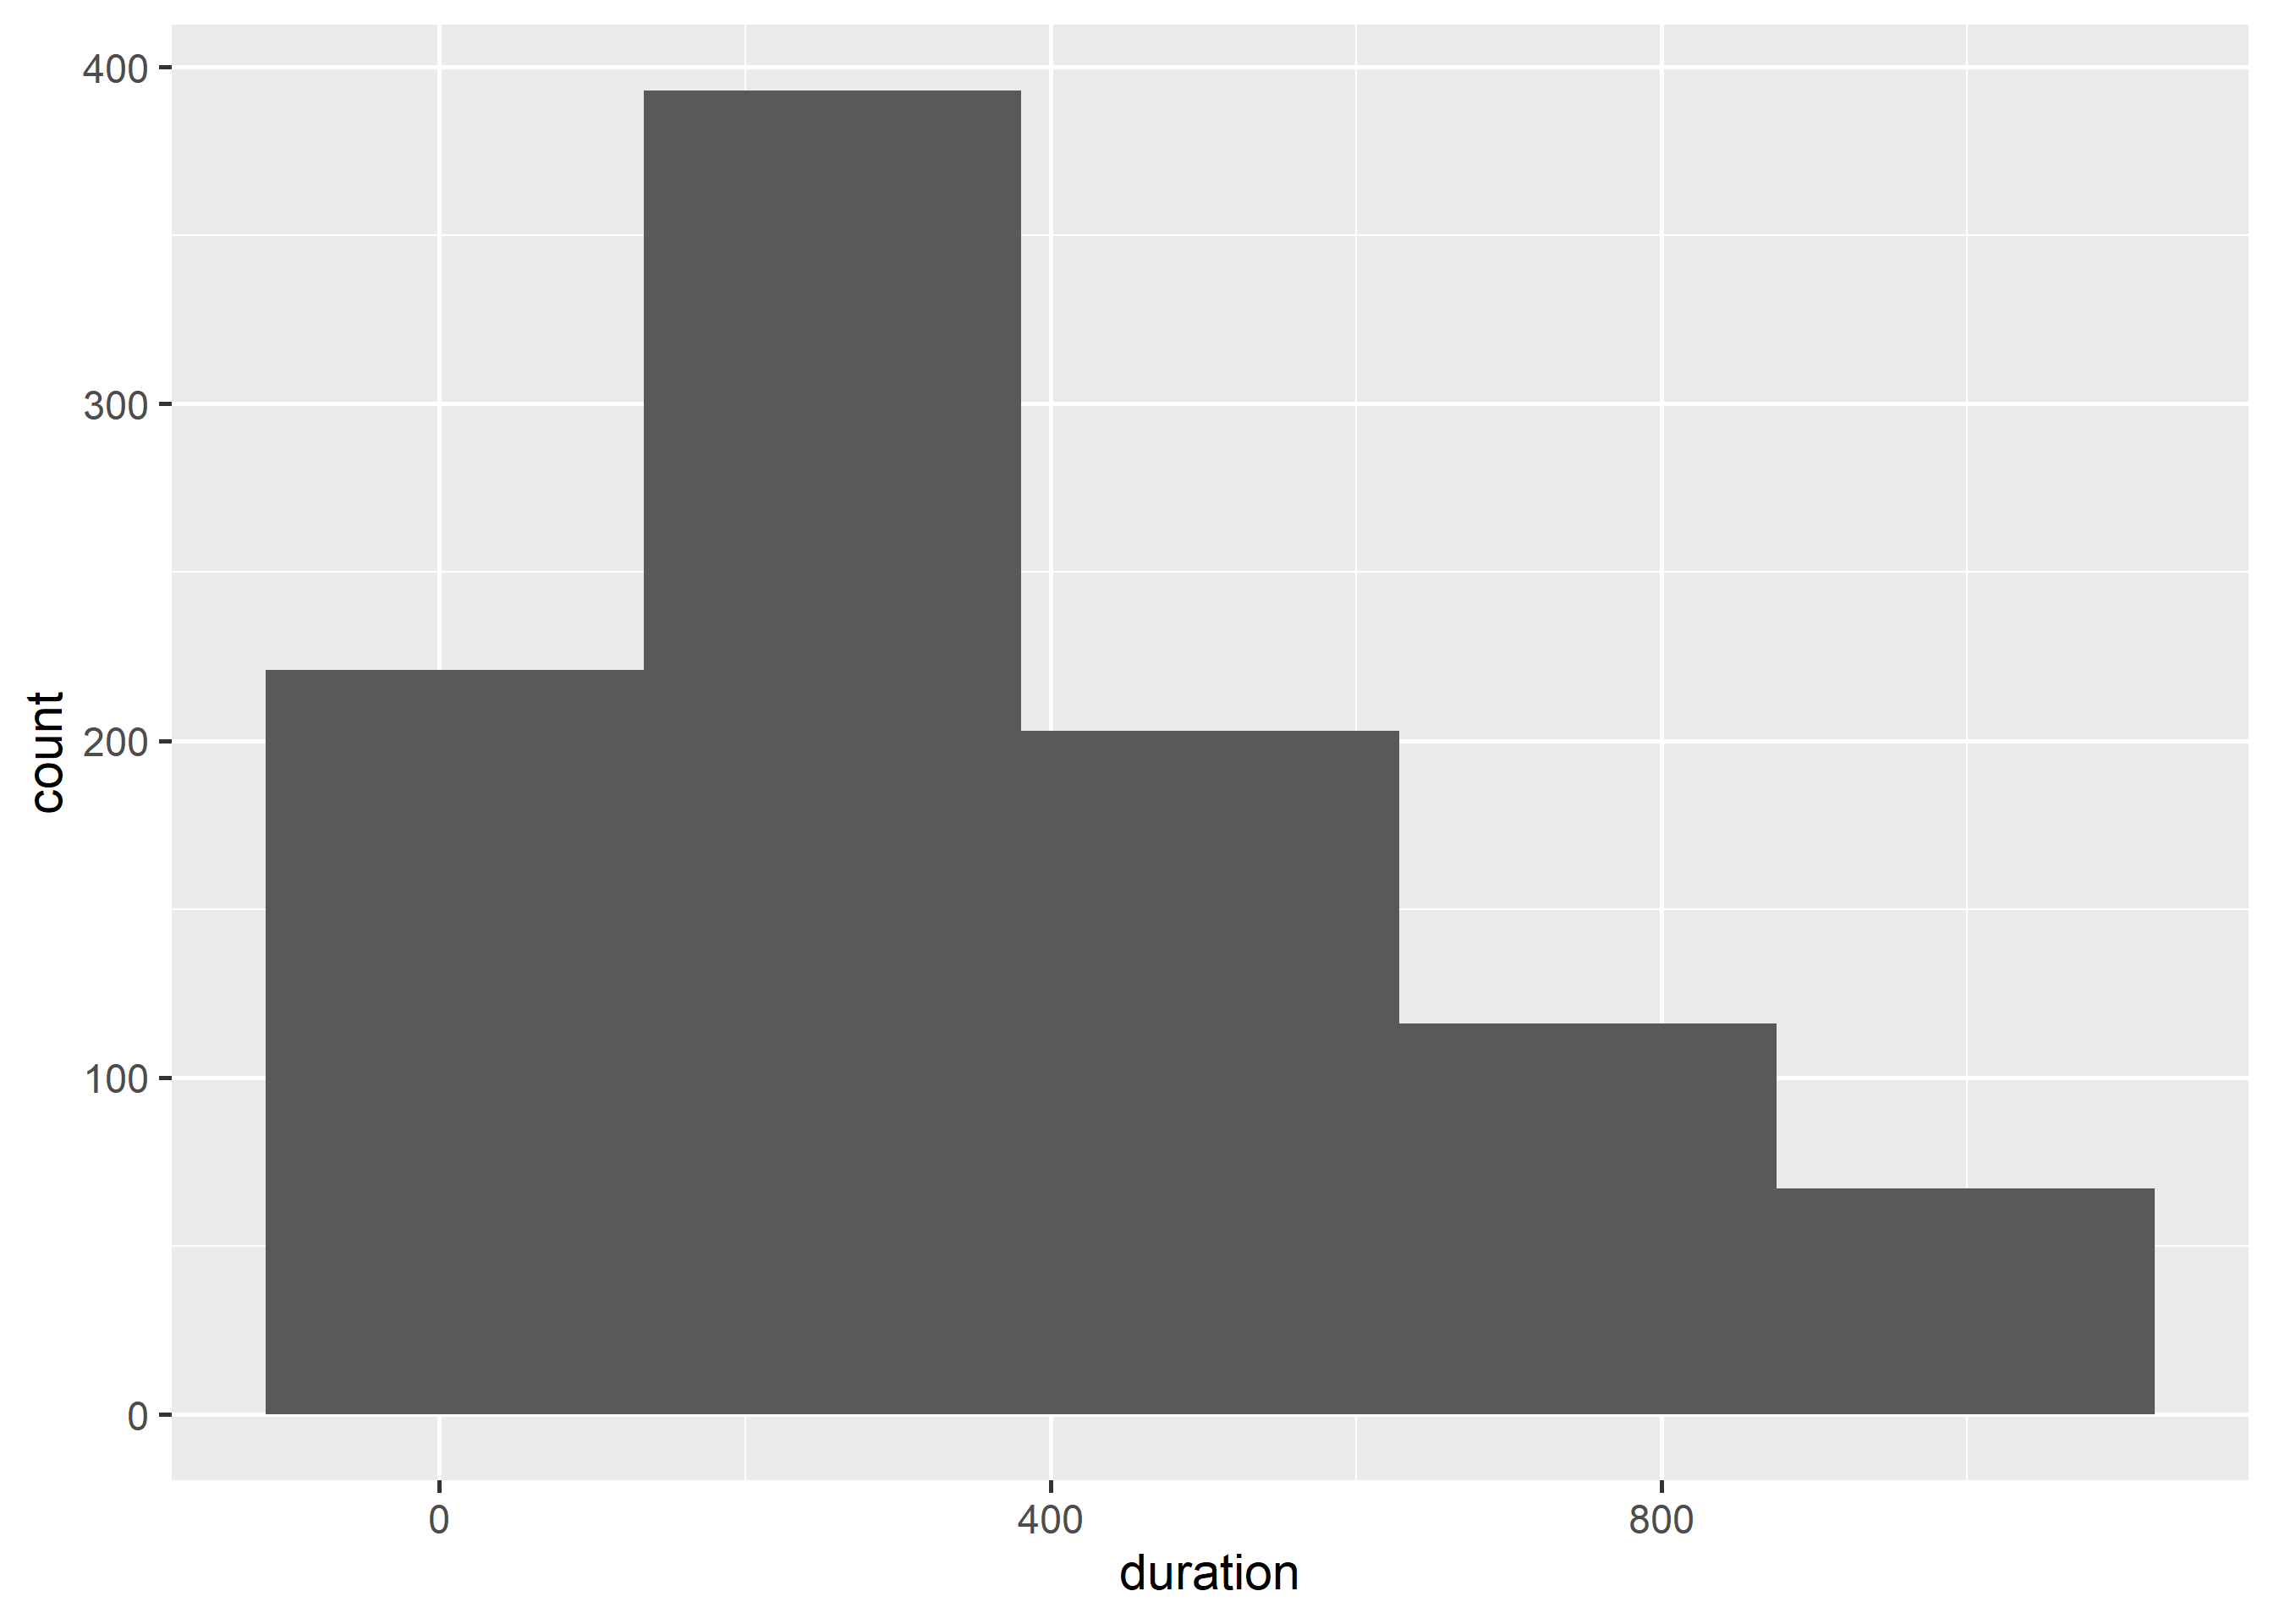
You can control the number of bins using the bins argument.